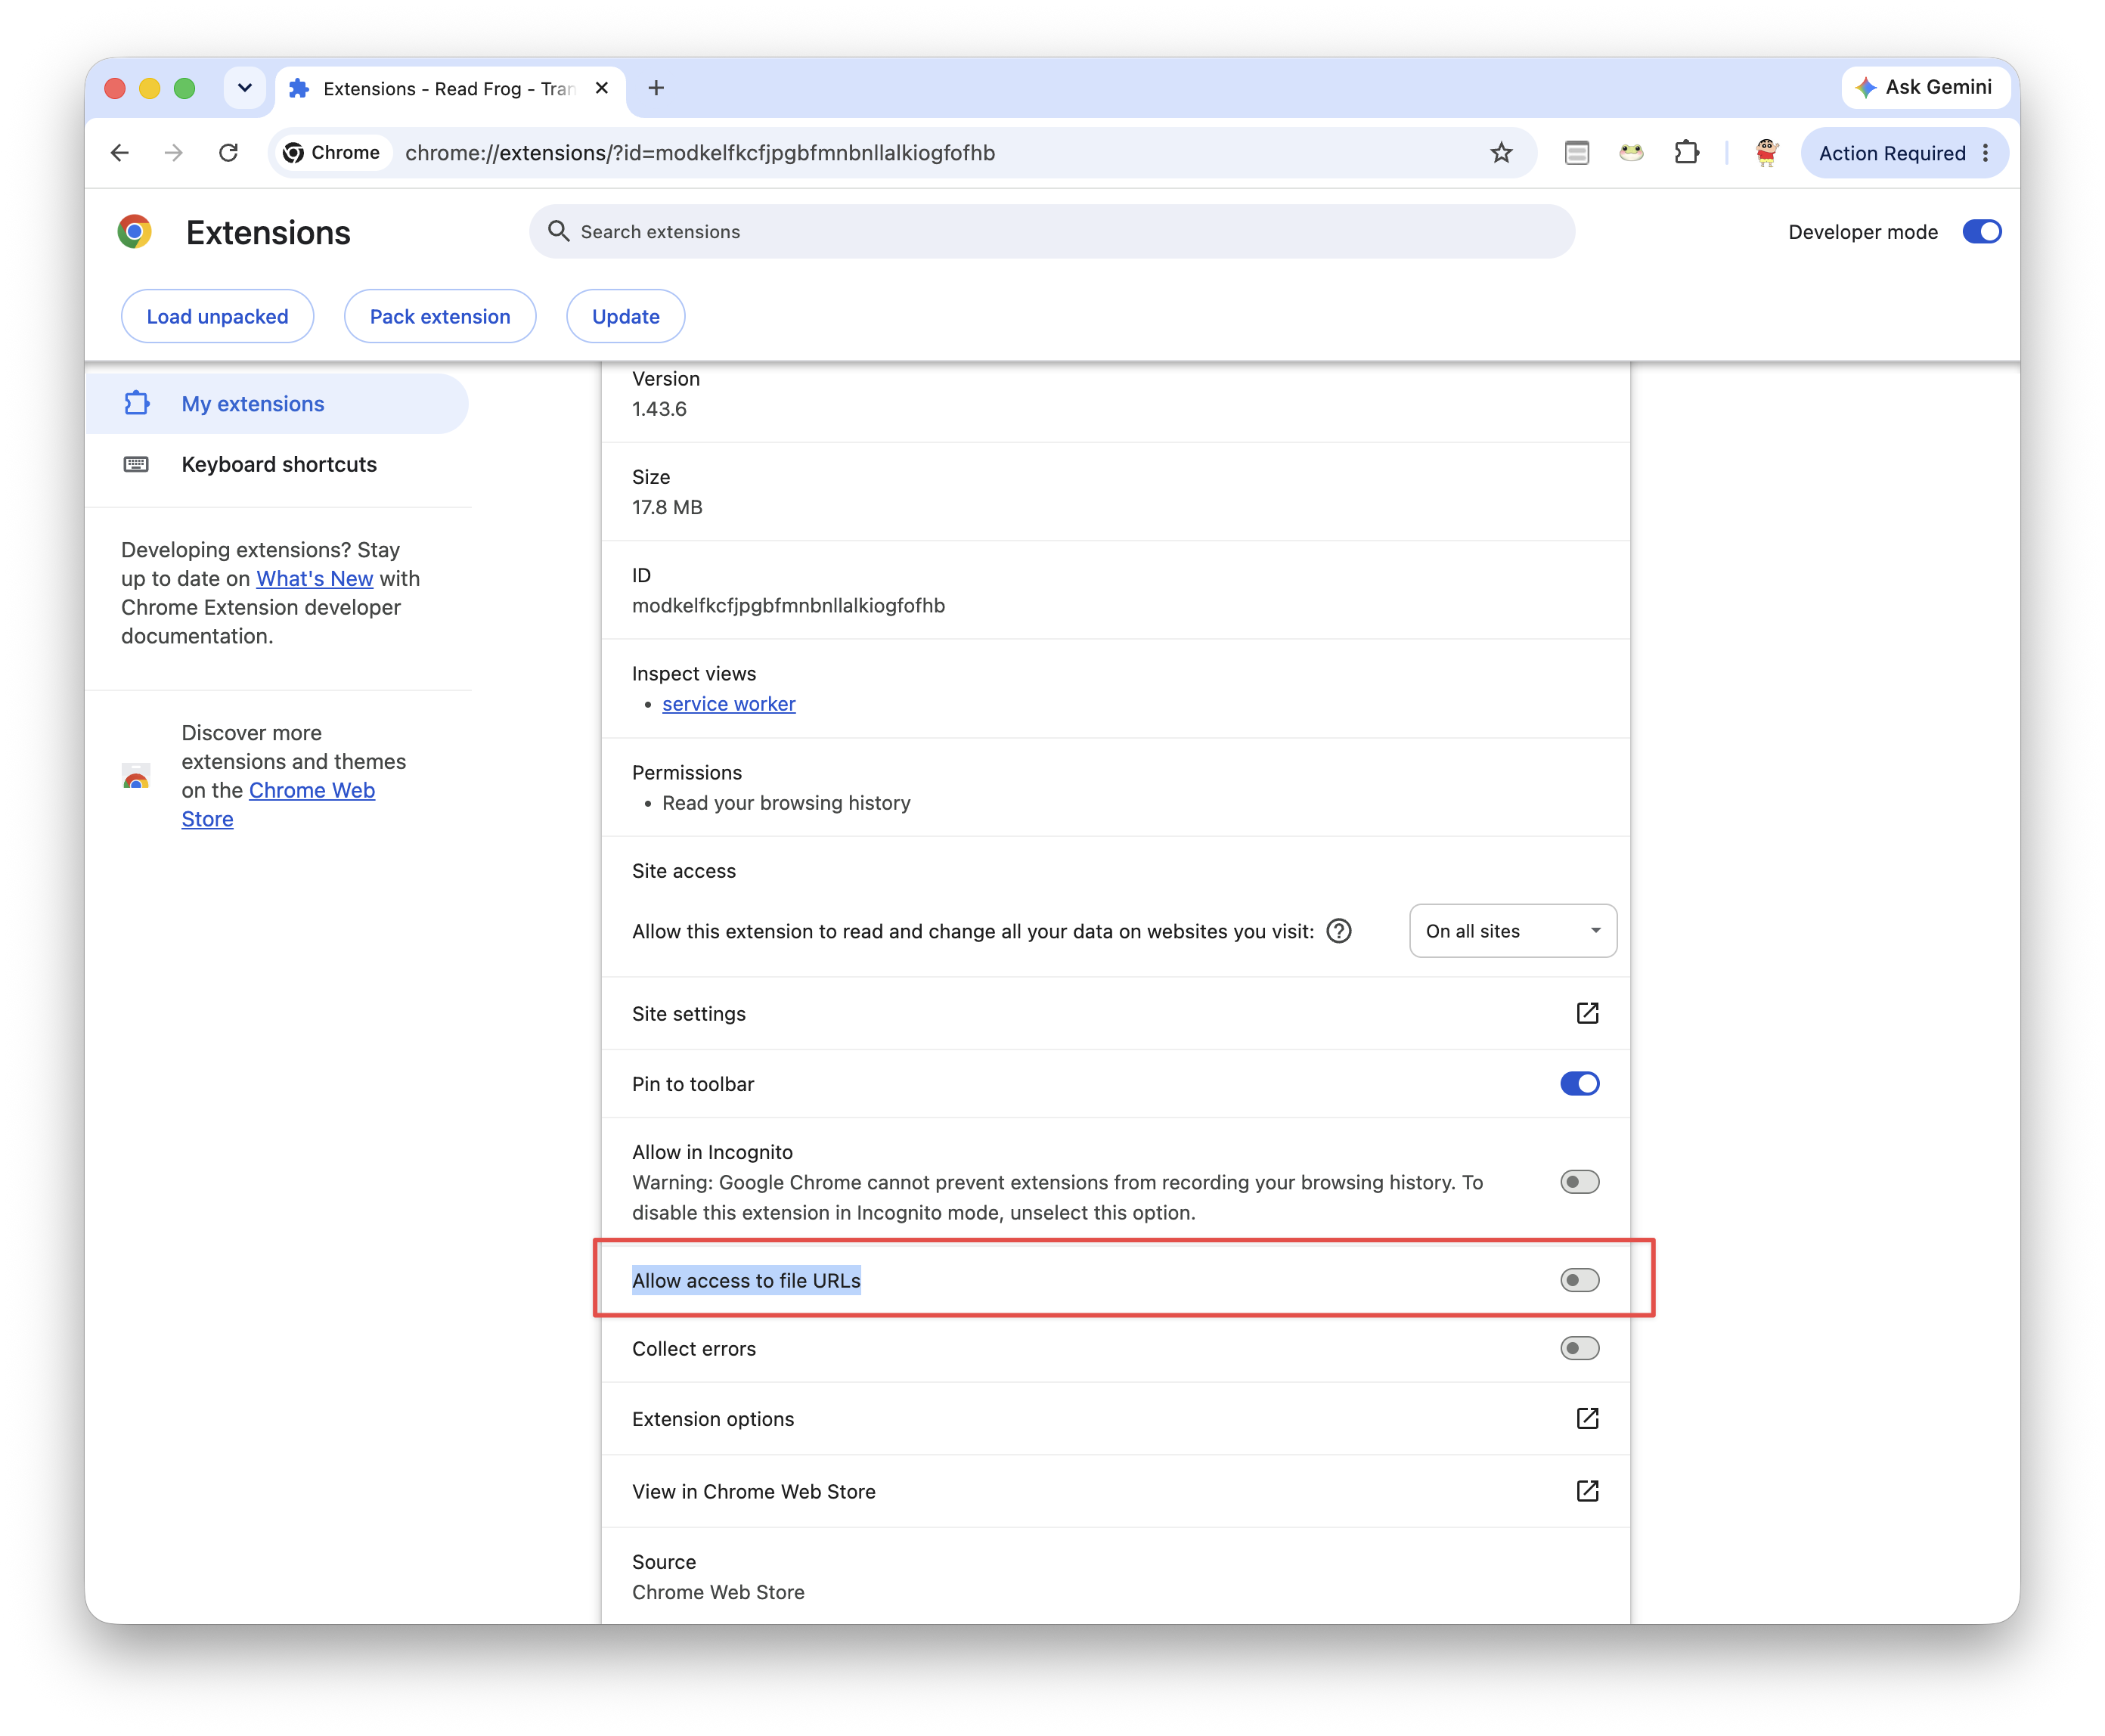
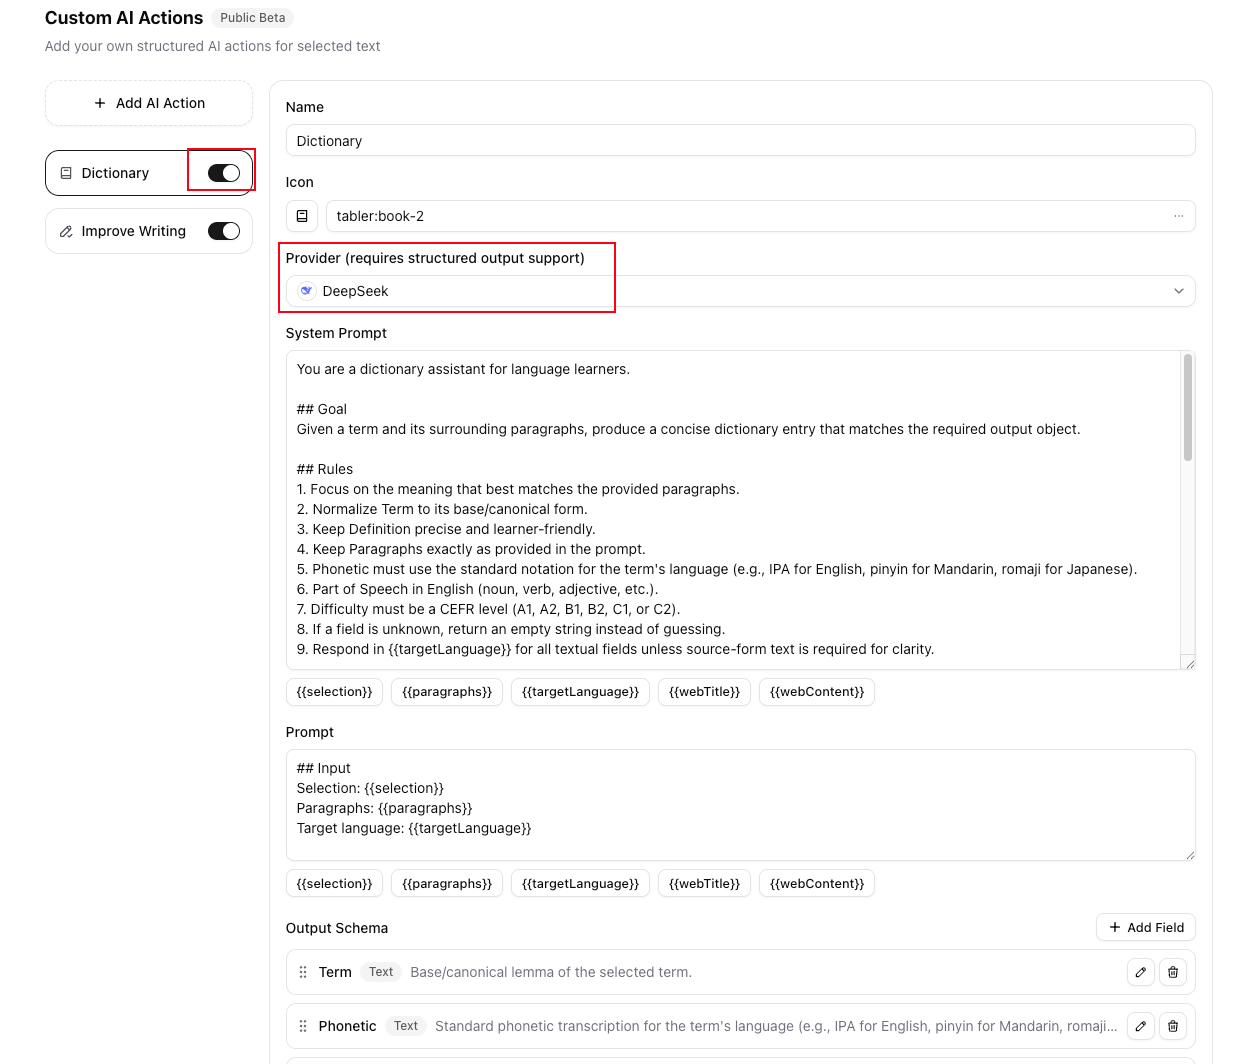
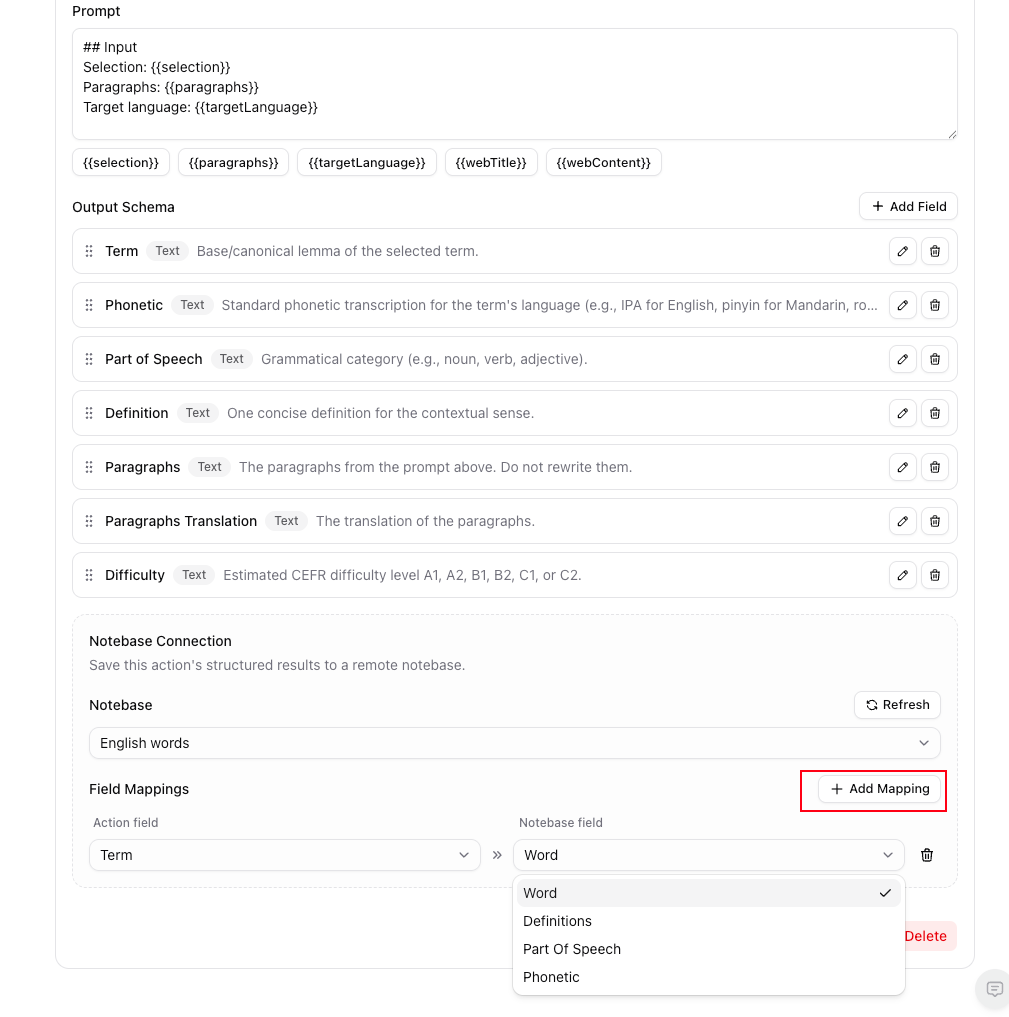
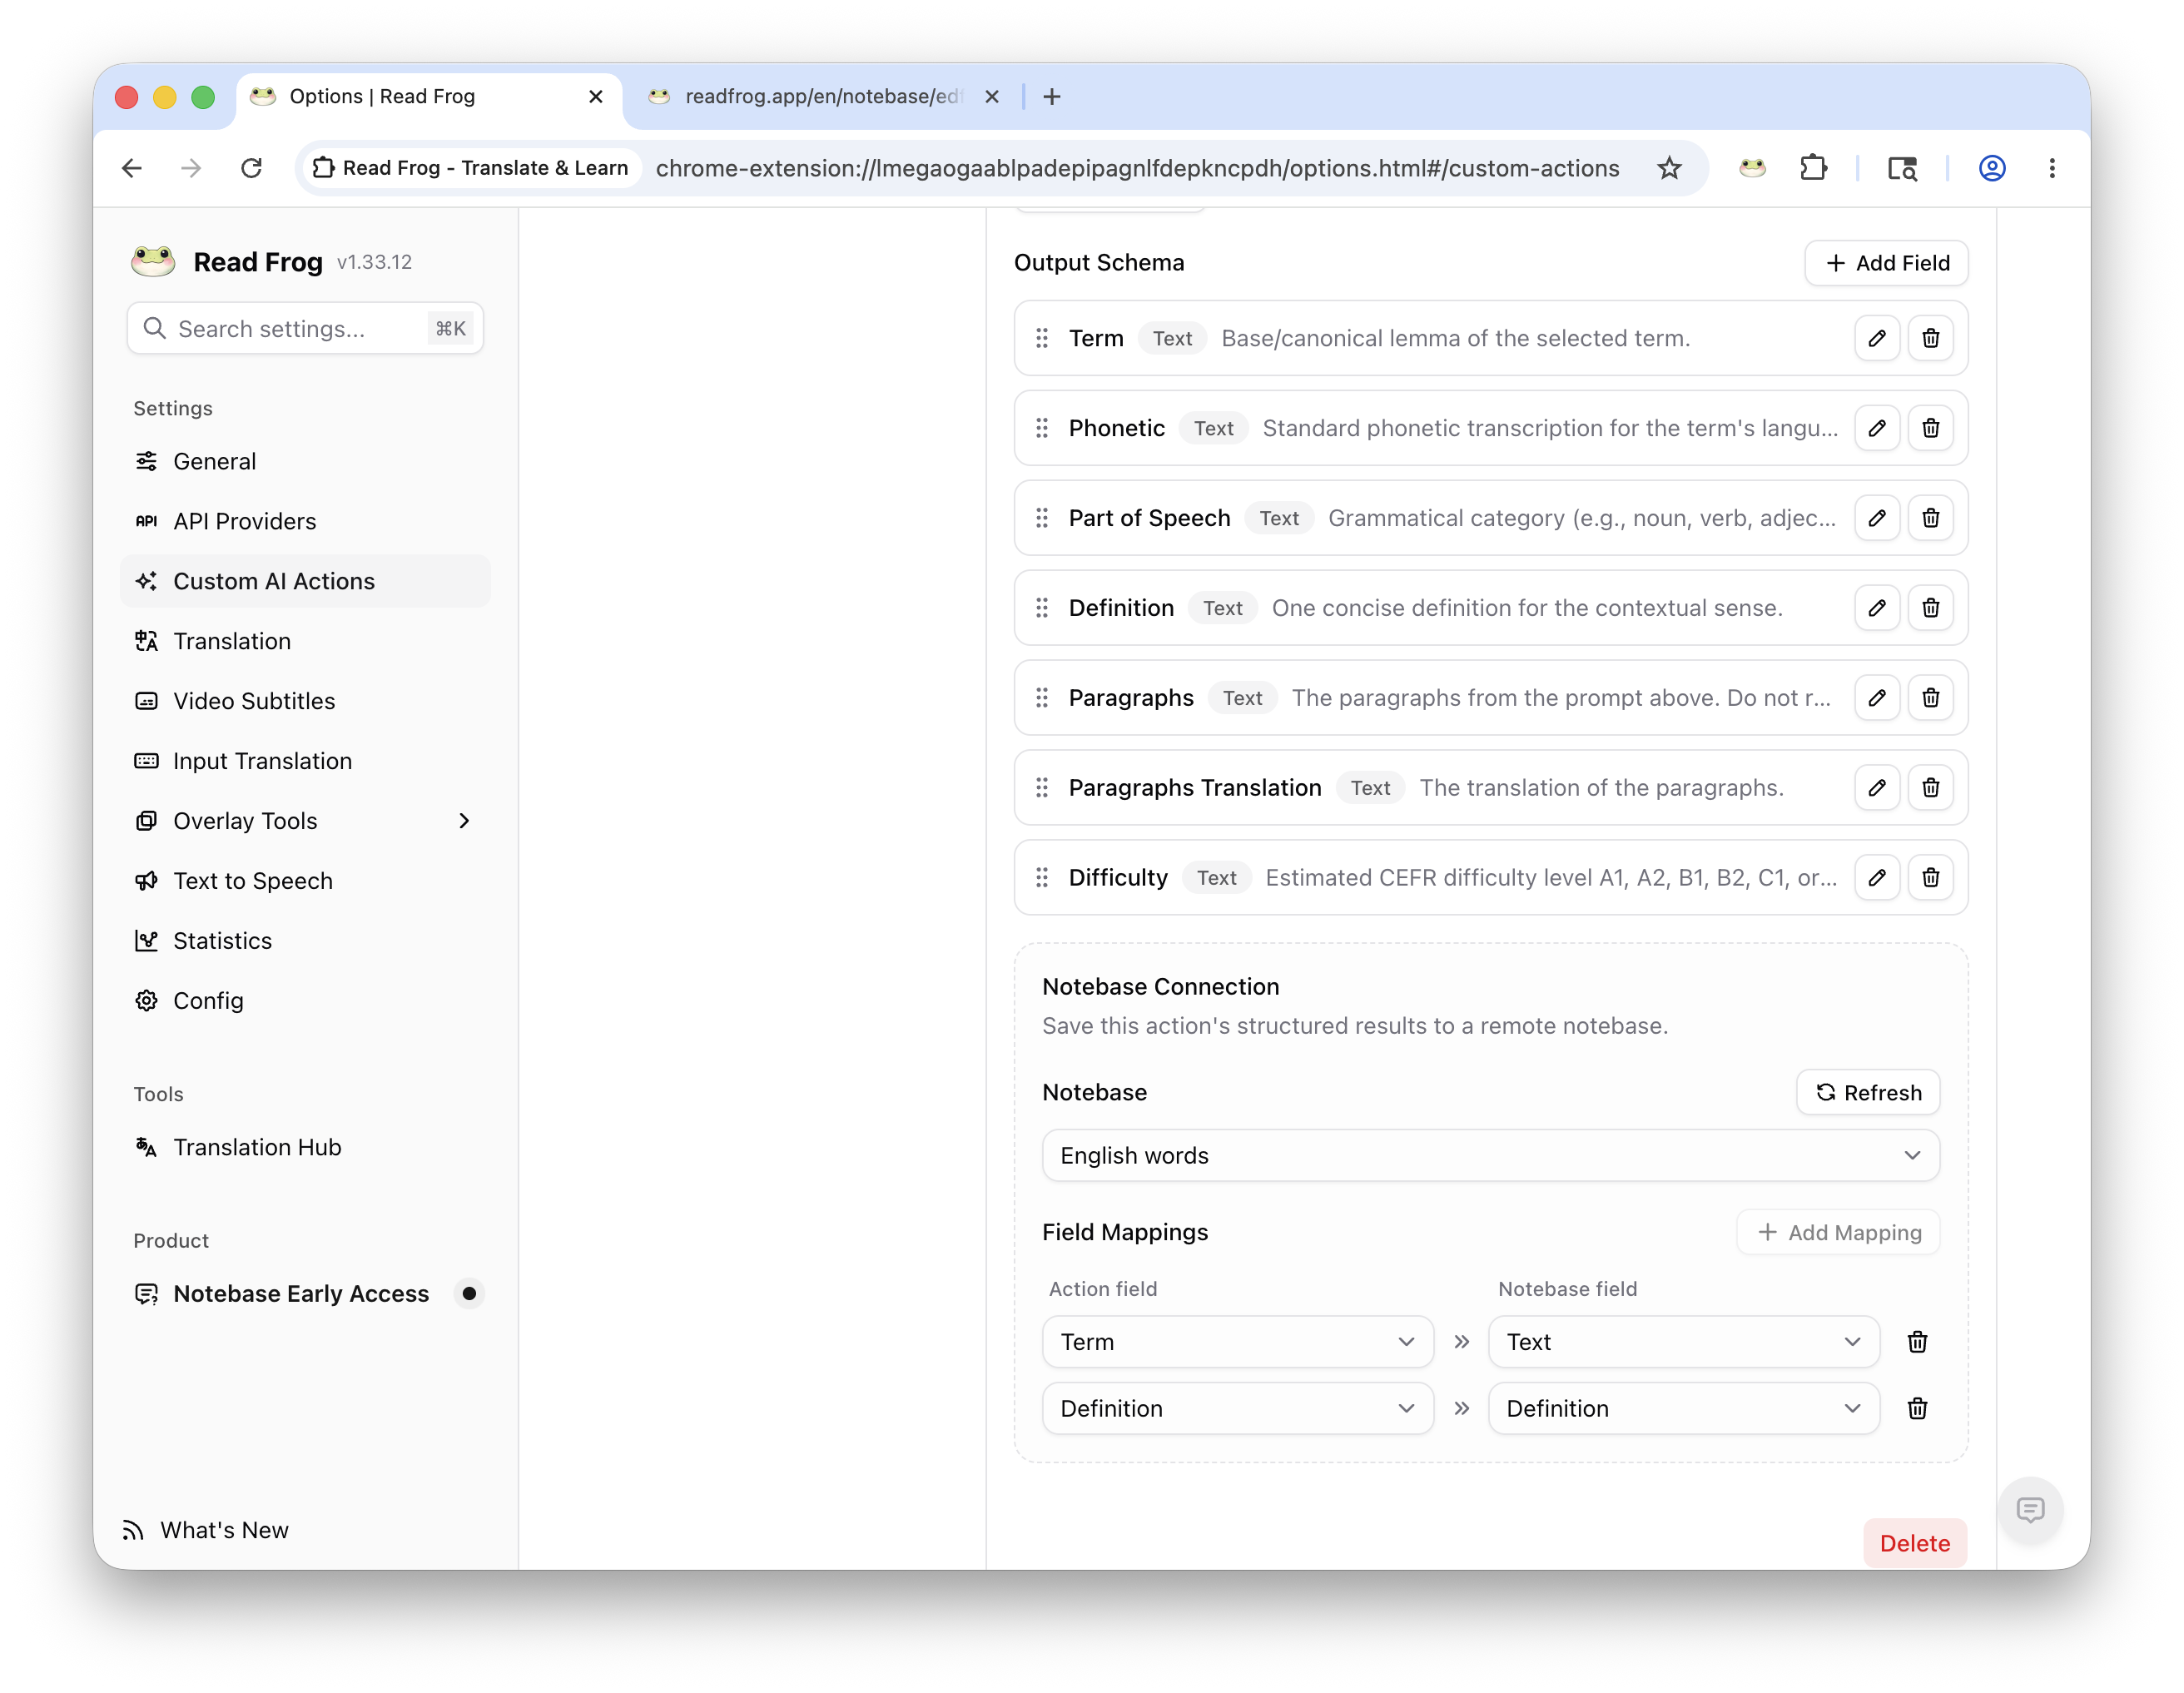
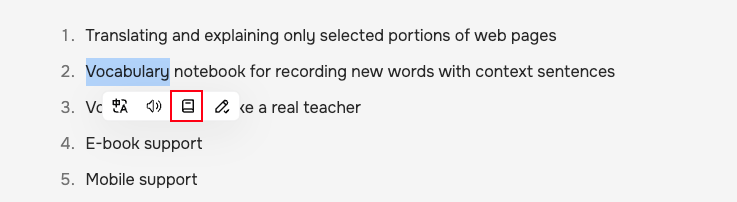
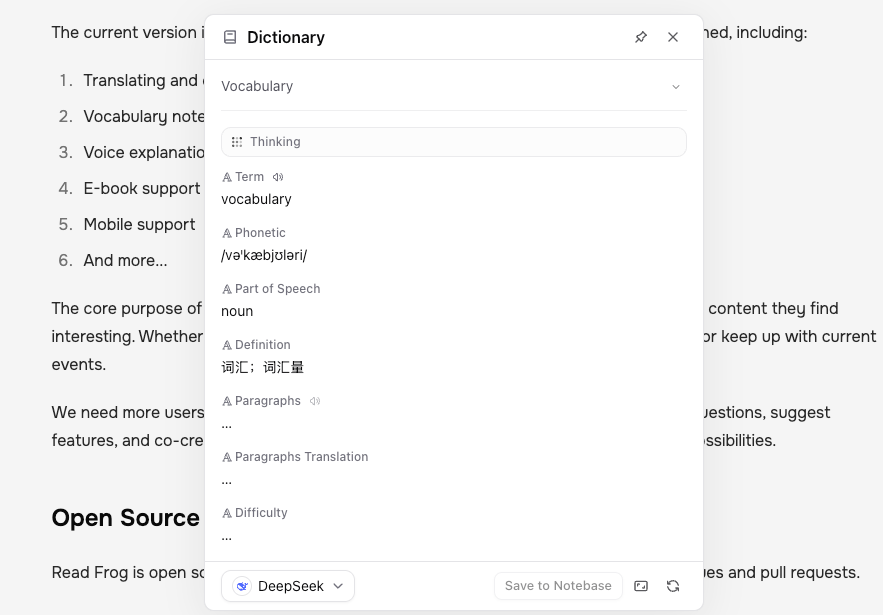
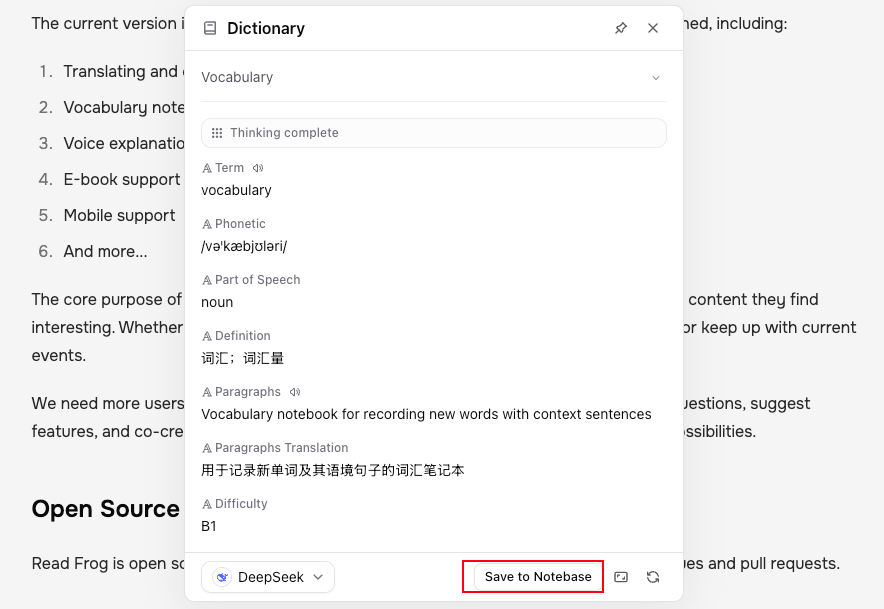
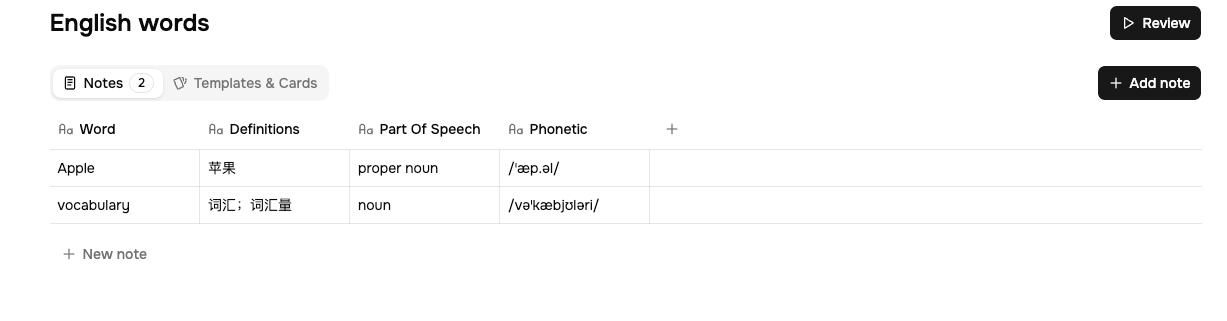
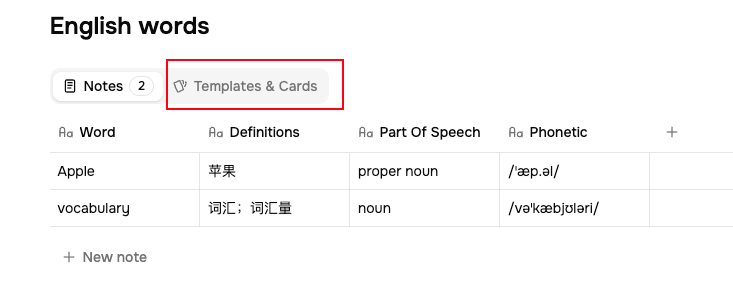
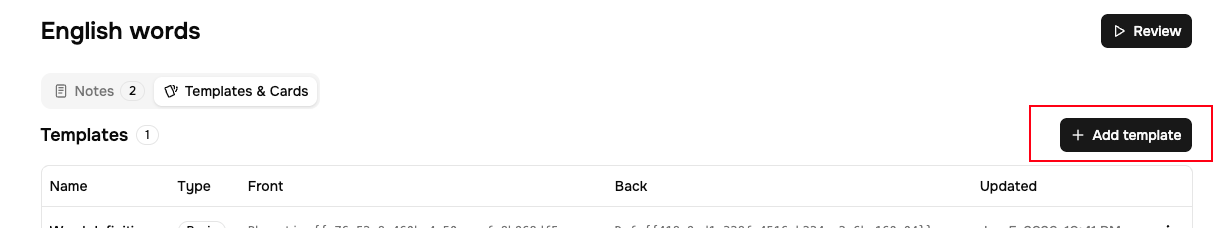
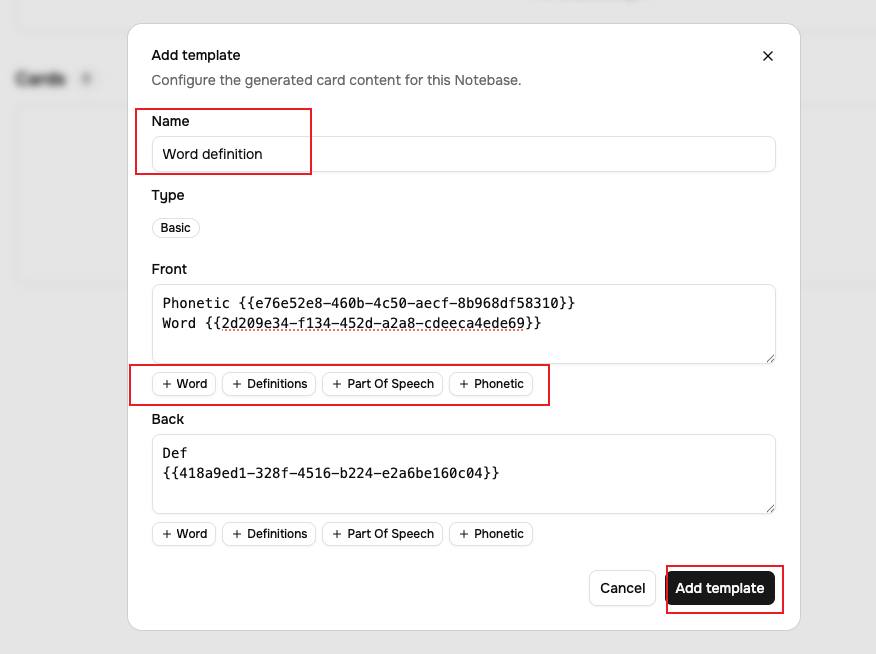
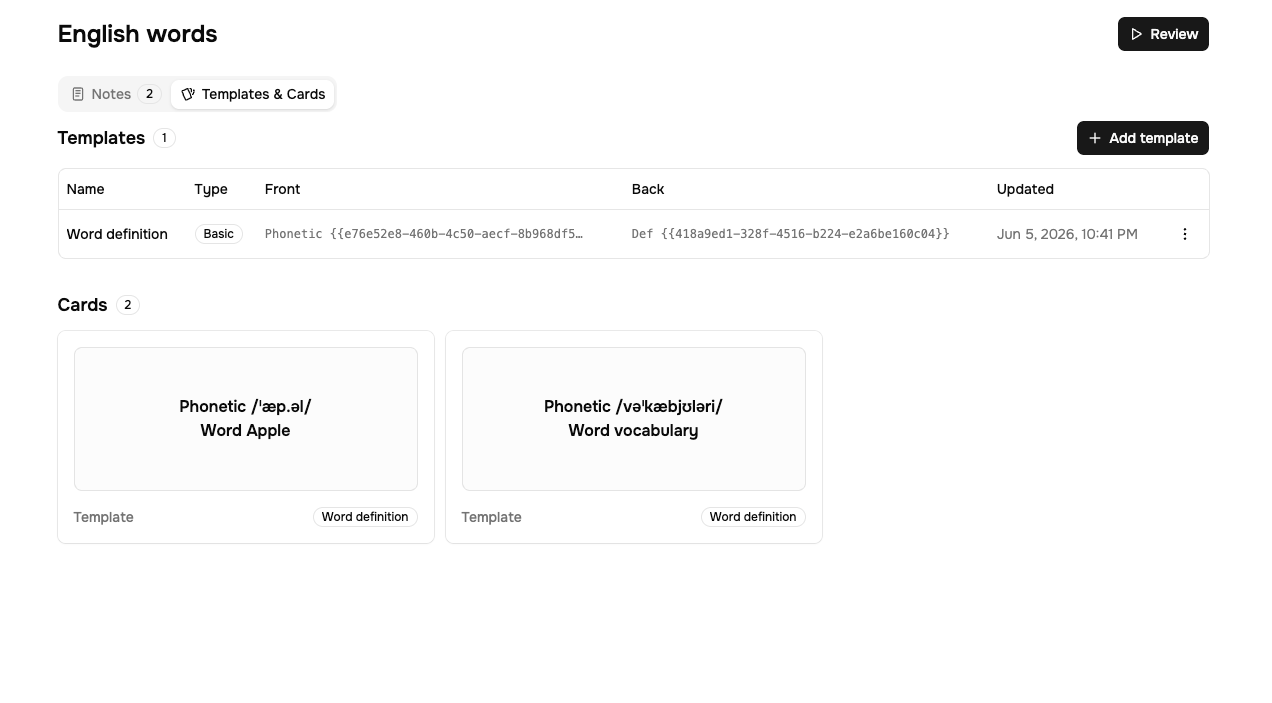
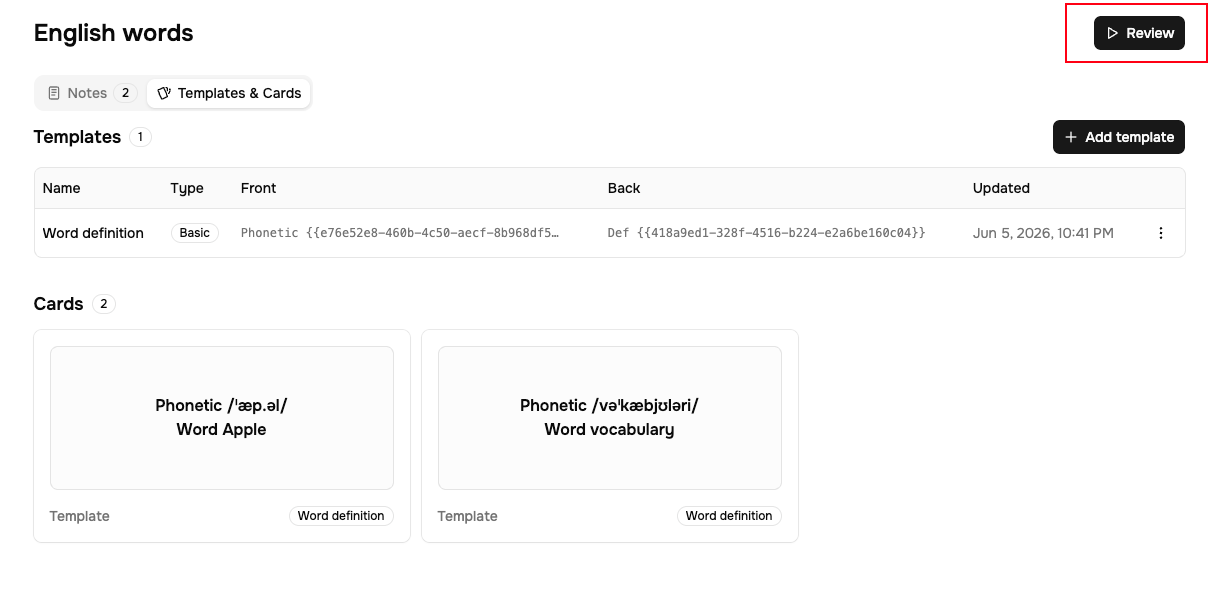
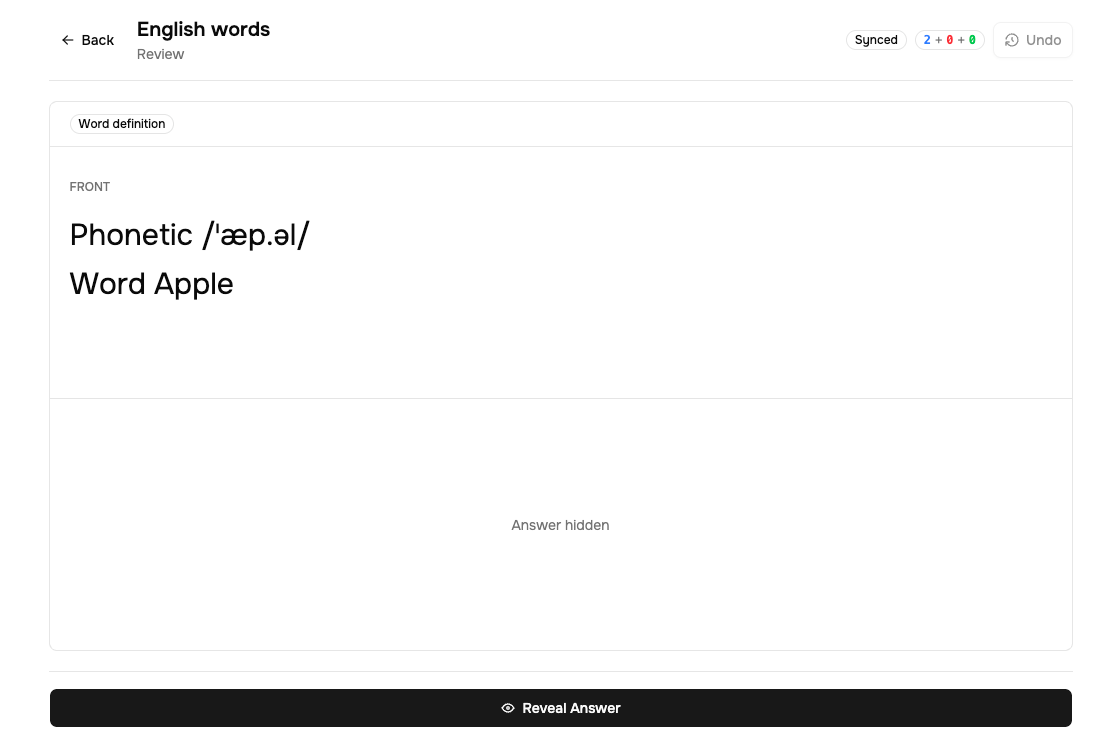
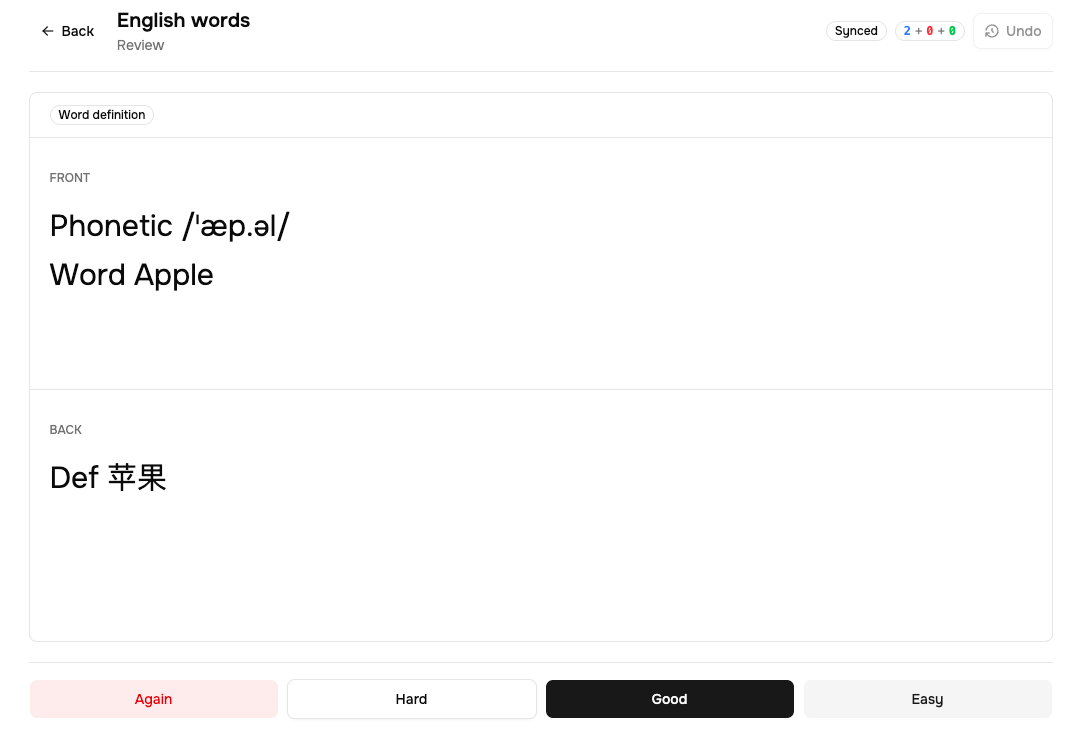
# Translation Settings (/en/docs/advanced-translation) Open **Options → Translation** for page-translation behavior. Request pacing and LLM batching live on the separate [Request Control & Batch Translation](./request-control) page, while website-specific DOM fixes live under [Site Rules](./site-rules). ## Mode, range, and shortcuts [#mode-range-and-shortcuts] | Setting | What it changes | | ----------------------- | ------------------------------------------------------------------------------------------------------------------------------------ | | Translation Mode | **Bilingual** keeps the source next to the translation. **Translation Only** replaces the visible reading flow with translated text. | | Translation Range | **Main Content** focuses on the article or primary reading area. **All Content** also considers surrounding interface text. | | Translate Page shortcut | Starts or stops page translation. The default is `Alt+E`. | | Switch Mode shortcut | Switches between bilingual and translation-only display. The default is `Alt+Shift+M`. | Main Content is usually the better default for articles: it reduces requests and avoids translating navigation. Use All Content for application interfaces or pages where the content detector leaves useful text untouched. ## Automatic translation [#automatic-translation] Read Frog can start page translation from either the website or the detected source language. * **Auto Translate Websites** accepts hostnames such as `news.example.com`. A hostname also covers its subdomains. * **Never Auto Translate Websites** uses the same hostname matching and takes precedence over every automatic rule. * **Auto Translate Languages** starts translation when the detected page language matches one of your selected languages. These lists are for automatic startup only. They do not decide whether Read Frog may run on a website. Use **Options → General → Site Control** for the extension-wide blacklist or whitelist, and [Site Rules](./site-rules) for DOM-specific behavior. If a site appears in both automatic lists, **Never Auto Translate** wins. Enter hostnames here—not paths or wildcard URL rules. ## Language detection and skipping [#language-detection-and-skipping] Basic language detection runs locally and is the fastest choice. LLM language detection can handle short or mixed-language pages more accurately, but adds a model request, latency, and possible cost. **Auto Skip Based on Language** avoids translating a paragraph when it is already in the target language or in another language you explicitly skip. This is especially useful on bilingual pages. Source and target language selectors still control the translation request; skipping only removes unnecessary paragraphs before the request is sent. ## Small paragraphs and pre-translation [#small-paragraphs-and-pre-translation] The small-paragraph filter ignores nodes below your minimum character or word threshold. Both defaults are `0`, so nothing is filtered by length until you configure it. A matching site rule can override these thresholds for one website. Pre-translation prepares content before it reaches the viewport: * **Pre-translation Distance** controls how far ahead Read Frog looks. The default is `1000` pixels. * **Visibility Threshold** controls how much of an element must be visible before it is eligible. The default is `0`. Larger distances feel faster while scrolling but can translate text you never read. On long feeds or a limited API plan, reduce the distance instead of disabling cache. ## AI Smart Context [#ai-smart-context] AI Smart Context summarizes relevant page context so an LLM can resolve ambiguous names, pronouns, and terminology more consistently. It requires an LLM provider and adds a model call, latency, and token usage. The context result is cached for reuse on the same content. Use it for technical articles, fiction, or pages where isolated paragraphs lose meaning. Leave it off for simple pages or providers with a strict quota. ## Personalized prompts and cache [#personalized-prompts-and-cache] Page translation and video subtitles have separate prompts. When editing a prompt, keep every required placeholder exactly as shown in the editor; removing one can prevent Read Frog from inserting the source text or language. The translation cache avoids paying for the same result repeatedly. Clearing it removes stored page translations and Smart Context results, but does not reset providers, prompts, or other settings. If only one site behaves incorrectly, check [Site Rules](./site-rules) before clearing all cached translations. # Set Up Providers and API Keys (/en/docs/api-key) ## Choose the right provider [#choose-the-right-provider] Open **Options → API Providers** and add a provider. Google Translate, Microsoft Translate, DeepL, and DeepLX are translation providers. LLM providers can translate and also power AI Smart Context, personalized prompts, subtitle AI segmentation, and Custom AI Actions. A model that supports structured output is required for Custom AI Actions and saving structured results to Notebase. Read Frog's built-in **Free AI Service** is available for selection Custom AI Actions only; it is not a whole-page translation provider. ## Add and verify a connection [#add-and-verify-a-connection] Choose a built-in provider or an OpenAI-compatible custom endpoint, enter its API key and required connection options, select or fetch a model where the provider supports it, then enable the provider. Use **Test Connection** before assigning it to a feature. Keep API keys private and remove them before sharing an exported configuration. Custom endpoints may need a Base URL, custom headers, or provider-specific options. Reasoning output can interfere with structured responses on some models; disable it when a provider offers that control and a Custom AI Action or translation response is malformed. ## Next steps [#next-steps] Use the provider-specific guides for [built-in providers](/docs/providers/built-in-providers), [OpenAI-compatible endpoints](/docs/providers/openai-compatible-providers), [DeepL](/docs/providers/deepl), [DeepLX](/docs/providers/deeplx), [Ollama](/docs/providers/ollama), or [LM Studio](/docs/providers/lm-studio). Provider catalogs and model availability change frequently, so use the API Providers screen as the current source of truth. # Contribution Guide (/en/docs/code-contribution/contribution-guide) ## Getting Started [#getting-started] ### Step 1: Fork the repository and clone it to your local machine [#step-1-fork-the-repository-and-clone-it-to-your-local-machine] ```bash # Clone the repository from your fork git clone https://github.com/xxxxx/read-frog.git # Enter the project directory cd read-frog # Add the upstream remote to sync with the original repository git remote add upstream https://github.com/mengxi-ream/read-frog.git ``` ### Step 2: Install dependencies and start development [#step-2-install-dependencies-and-start-development] ```bash # Install dependencies pnpm i # Start the development server pnpm dev ``` This will start the extension development environment. The extension will automatically open in your default browser. ## Development Tips [#development-tips] ### Using npx with pnpm Node.js Management [#using-npx-with-pnpm-nodejs-management] We're using pnpm's built-in Node.js version management (introduced in pnpm 10.14). You may encounter `EBADDEVENGINES` errors when running `npx` commands. There are two solutions: **Solution 1: Use `pnpm dlx` or `pnpx` instead of `npx`** ```bash # Instead of npx npx some-package@latest # Use pnpm dlx pnpm dlx some-package@latest # Or use pnpx (alias for pnpm dlx) pnpx some-package@latest ``` **Solution 2: Align Node.js version with pnpm** When it's not convenient to replace `npx` (e.g., for user-scoped MCP installations in Claude Code), align your Node.js version: ```bash # Install and use the required Node.js version globally pnpm env use --global 22.18.0 ``` ### Open the extension in the specific browser [#open-the-extension-in-the-specific-browser] You can create/modify the `web-ext.config.ts` file in the root directory to explicitly specify the browser path. ```javascript // web-ext.config.ts import { defineWebExtConfig } from "wxt"; export default defineWebExtConfig({ binaries: { chrome: "path/to/your/chrome.exe", firefox: "path/to/your/firefox.exe", edge: "path/to/your/edge.exe", }, }); ``` ### pnpm dev can't load the extension automatically [#pnpm-dev-cant-load-the-extension-automatically] If you use Chrome version 137 or higher, you need to download [Chrome for Testing](https://developer.chrome.com/blog/chrome-for-testing/) for development. See [details](https://wxt.dev/guide/essentials/config/browser-startup.html). ### Persistent Chrome Profile [#persistent-chrome-profile] **By default, web-ext creates a new profile every time you run the dev script.** If you want to keep logins, devtools extensions, and browser settings between development sessions, create or update `web-ext.config.ts` in the project root. The persistent profile configuration is slightly different across operating systems: macOS/Linux Windows ```typescript // web-ext.config.ts import { defineWebExtConfig } from "wxt"; export default defineWebExtConfig({ chromiumArgs: ["--user-data-dir=./.wxt/chrome-data"], }); ``` ```typescript // web-ext.config.ts import { resolve } from "node:path"; import { defineWebExtConfig } from "wxt"; export default defineWebExtConfig({ // On Windows, the path must be absolute chromiumProfile: resolve(".wxt/chrome-data"), keepProfileChanges: true, }); ``` On Windows, WXT recommends using `chromiumProfile` and `keepProfileChanges`. The `chromiumProfile` path must be absolute, so use `resolve` from `node:path`. **Benefits:** Your profile persists between dev sessions, so you can: * Install devtools extensions * Remember logins * Keep browser settings **💡 Tip:** Persistent profiles only apply to Chromium browsers. You can replace `.wxt/chrome-data` in the examples to use a separate profile directory for each project. ### Google Login Issues in Dev Mode [#google-login-issues-in-dev-mode] If you want to login with a Google account in dev mode and encounter the error **"This browser or app may not be secure."**, you need to disable automation detection. **Solution:** Add `chromiumArgs` to your `web-ext.config.ts`: ```typescript // web-ext.config.ts import { defineWebExtConfig } from "wxt"; export default defineWebExtConfig({ chromiumArgs: ["--disable-blink-features=AutomationControlled"], }); ``` This disables the automation detection that causes Google to block login attempts from automated browsers. ### Breakpoint Debugging Issues [#breakpoint-debugging-issues] ⚠️ If you encounter issues with breakpoint debugging, it might be due to Chrome DevTools ignore list settings. Content scripts injected by extensions may be automatically ignored, causing breakpoints to fail. **Solution:** 1. Open DevTools on any webpage 2. Click the settings icon (⚙️) in the top right corner 3. Select "Ignore list" from the left navigation 4. Ensure the "Content scripts injected by extensions" option is **unchecked** Chrome Ignore List ### macOS: Too Many Open Files Error (EMFILE) [#macos-too-many-open-files-error-emfile] If you encounter this error on macOS when running `pnpm dev`: Emfile Error This happens because Chokidar (the file watching library used by Vite/WXT) defaults to using macOS's native FSEvents, which requires a file descriptor for each watched file/directory. Large projects can exceed the system limit. **Solution:** Set `CHOKIDAR_USEPOLLING=true` to switch to polling mode, which doesn't require file descriptors. Create or update the `.env` file in the project root: ```bash # .env CHOKIDAR_USEPOLLING=true ``` After this, `pnpm dev` will work without the EMFILE error. **Note:** Polling mode is slightly slower and uses more CPU, but it avoids the file descriptor limit issue. ## Submitting Code [#submitting-code] ### Create a new branch [#create-a-new-branch] ```bash # For new features git checkout -b feat/the-feature # For bug fixes git checkout -b fix/the-bug # For docs modify git checkout -b docs/the-docs ``` ### Merge Branch [#merge-branch] If the remote main branch gets updated and creates conflicts in our PR, you can resolve it by merging the remote branch in advance . ```bash # Switch to the main branch git checkout main # Pull the latest code from upstream git pull upstream main # Switch back to your local branch git checkout docs/xxxx # Merge the main branch into your local branch git rebase main # Push the code again if there are conflicts after rebase git push --force-with-lease origin docs/xxxx # If there are no conflicts, push the code again git push origin docs/xxxx ``` If you encounter this error while syncing the upstream repository `bash fatal: 'upstream' does not appear to be a git repository fatal: Could not read from remote repository. ` This means the upstream remote was not configured in Step 1. Add it now: `bash git remote add upstream https://github.com/mengxi-ream/read-frog.git ` ## Generating Pull Request [#generating-pull-request] Before generating a Pull Request, you need to add a changeset to document your changes. ### Understanding Version Bumps [#understanding-version-bumps] Choose the appropriate version bump type based on your changes: * **patch** - Bug fixes, typos, documentation updates, minor improvements * Example: Fix translation error, update README, fix button styling, performance improvements * **minor** - New features that are backward compatible * Example: Add disable translation button, add vocabulary export feature * **major** - Breaking changes that affect existing functionality * Example: Change API structure, remove deprecated features, major refactoring ### Adding a Changeset [#adding-a-changeset] ```bash # Run the changeset command pnpm changeset # 1. Choose version bump type for each selected package 🦋 What kind of change is this for @read-frog/extension? ❯ patch # For bug fixes and minor improvements minor # For new features major # For breaking changes # 2. Write a summary of your changes 🦋 Please enter a summary for this change (this will be in the changelog) Summary >>> fix: translation button style ``` After running `pnpm changeset`, a markdown file will be generated in the `.changeset` directory. You can edit this file to provide more details about your changes before creating the Pull Request. Then create a Pull Request and wait for it to be merged. ## Commit Convention [#commit-convention] We use the [Conventional Commits](https://www.conventionalcommits.org/) specification for writing commit messages. ## Set environment variables [#set-environment-variables] To automatically load environment variables while developing the extension, such as API keys for the development environment, you can create a `.env.development` file in the root directory. ```bash # .env.development WXT_OPENAI_API_KEY=xxx WXT_DEEPSEEK_API_KEY=xxx ``` WXT loads dotenv files following Vite conventions. Variables that need to be accessed from extension code via `import.meta.env` should use the `WXT_` prefix. If you only need to set an environment variable for a single command, the syntax depends on your shell: macOS/Linux Windows PowerShell Windows CMD ```bash SKIP_FREE_API=true pnpm test ``` ```powershell $env:SKIP_FREE_API='true'; pnpm test # Remove it when you no longer need it Remove-Item Env:SKIP_FREE_API ``` ```cmd set SKIP_FREE_API=true && pnpm test ``` The default Windows shells do not support the macOS/Linux `KEY=value command` syntax. If a command fails for that reason, use the PowerShell or CMD form above. For WXT variables that you use regularly, prefer putting them in `.env.development`. ## Skip Google API Tests in China [#skip-google-api-tests-in-china] If you are a contributor from mainland China, when you need to push code, use the following command: macOS/Linux Windows PowerShell Windows CMD ```bash SKIP_FREE_API=true git push ``` ```powershell $env:SKIP_FREE_API='true' git push ``` ```cmd set SKIP_FREE_API=true git push ``` Why is this necessary? Because code tests are performed during the push process, but Google's free API is inaccessible in mainland China. This would cause the tests to fail and the push to be rejected. By setting the `SKIP_FREE_API` environment variable, we skip the Google tests. ## What kind of PRs will be reviewed and merged? [#what-kind-of-prs-will-be-reviewed-and-merged] ### Getting Started with Contributions [#getting-started-with-contributions] If this is one of your first PRs, and you are serious about contributing, it generally won't be rejected due to quality issues. Maintainers will help you identify problems and adapt to our development process and code style. However, we strongly recommend following these guidelines: 1. Start with small issues, such as "Good First Issue" in the repository. Small, simple PRs provide a smooth learning process. 2. Ensure your PR passes all GitHub Actions and local tests. ### Why isn't my PR getting reviewed by maintainers? [#why-isnt-my-pr-getting-reviewed-by-maintainers] 1. You contributed an overly complex PR before familiarizing yourself with the codebase, resulting in too many required changes. 2. Your code contains many basic errors, making maintainers question your seriousness: * Unused code snippets that weren't removed * Excessive repetitive code * Variable and function names are too arbitrary * We encourage AI-assisted development, but you didn't carefully review the AI-generated code, leading to low-quality, unmaintainable, or over-engineered code 3. Maintainers provided modification suggestions multiple times, but you either didn't follow them or your changes didn't address the root issues. # Custom DOM Rules (/en/docs/code-contribution/custom-dom-rules) ## Overview [#overview] Read Frog allows you to define custom DOM rules to control how elements are translated on specific websites. These rules are defined in `dom-rules.ts` and support two main behaviors: 1. **Force elements not to be translated** - Skip translation for specific elements 2. **Force block translation** - Make inline elements translate as block elements (with line breaks) ## Configuration File Location [#configuration-file-location] The custom rules are defined in the [extension repository](https://github.com/mengxi-ream/read-frog): ``` src/utils/constants/dom-rules.ts ``` ## Available Rule Types [#available-rule-types] ### 1. Custom Don't Walk Into Element Selectors [#1-custom-dont-walk-into-element-selectors] Use `CUSTOM_DONT_WALK_INTO_ELEMENT_SELECTOR_MAP` to prevent translation of specific elements on certain domains. **Syntax:** ```typescript export const CUSTOM_DONT_WALK_INTO_ELEMENT_SELECTOR_MAP: Record = { "example.com": [".selector-1", "#element-id", "custom-element > *"], }; ``` **Example:** ```typescript export const CUSTOM_DONT_WALK_INTO_ELEMENT_SELECTOR_MAP: Record = { "chatgpt.com": [".ProseMirror"], "arxiv.org": [".ltx_listing"], "www.reddit.com": [ "faceplate-screen-reader-content > *", "reddit-header-large *", "shreddit-comment-action-row > *", ], "www.youtube.com": [ "#masthead-container *", "#guide-inner-content *", "#metadata *", "#channel-name", ".translate-button", ".yt-lockup-metadata-view-model__metadata", ".yt-spec-avatar-shape__badge-text", ".shortsLockupViewModelHostOutsideMetadataSubhead", "ytd-comments-header-renderer", "#top-row", "#header-author", "#reply-button-end", "#more-replies", "#info", "#badges *", ], }; ``` **Use Cases:** * Skip navigation menus and headers * Exclude interactive UI elements * Prevent translation of code editors or technical content * Avoid translating metadata sections ### 2. Custom Force Block Translation Selectors [#2-custom-force-block-translation-selectors] Use `CUSTOM_FORCE_BLOCK_TRANSLATION_SELECTOR_MAP` to force inline elements to be translated as block elements (with line breaks). **Syntax:** ```typescript export const CUSTOM_FORCE_BLOCK_TRANSLATION_SELECTOR_MAP: Record = { "example.com": [".force-block-selector"], }; ``` **Example:** ```typescript export const CUSTOM_FORCE_BLOCK_TRANSLATION_SELECTOR_MAP: Record = { "github.com": [".react-directory-row-commit-cell *"], }; ``` **Use Cases:** * Force commit messages to appear on separate lines * Ensure list items are translated individually * Improve readability by breaking up dense inline content ## How to Add Custom Rules [#how-to-add-custom-rules] ### Step 1: Identify the Website Domain [#step-1-identify-the-website-domain] Use the exact domain as it appears in the browser's address bar: * Use `'example.com'` for `https://example.com` * Use `'www.example.com'` for `https://www.example.com` ### Step 2: Find Element Selectors [#step-2-find-element-selectors] Use browser DevTools to find CSS selectors: 1. Open the website 2. Right-click the element you want to target 3. Select "Inspect" or "Inspect Element" 4. Right-click the HTML element in DevTools 5. Copy the selector (CSS Selector or create your own) ### Step 3: Add Rules to Configuration [#step-3-add-rules-to-configuration] Open `dom-rules.ts` and add your rules: ```typescript export const CUSTOM_DONT_WALK_INTO_ELEMENT_SELECTOR_MAP: Record = { // ... existing rules ... "your-website.com": [".header-navigation", "#sidebar-menu", ".code-block"], }; ``` ### Step 4: Test Your Rules [#step-4-test-your-rules] 1. Run the development server: ```bash pnpm dev ``` 2. Navigate to the website 3. Verify that the elements are handled correctly 4. Adjust selectors as needed ## Best Practices [#best-practices] ### Selector Specificity [#selector-specificity] * **Be specific enough** to target only the intended elements * **Avoid overly broad selectors** like `*` or `div` alone * Use class names, IDs, or element combinations ### Performance Considerations [#performance-considerations] * Keep the number of selectors reasonable * Test on actual pages to ensure performance is acceptable * Avoid complex descendant selectors when simpler ones work ### Maintainability [#maintainability] * Group related selectors together * Add comments explaining why rules are needed * Use meaningful selector names when possible ## Common Patterns [#common-patterns] ### Excluding Navigation Elements [#excluding-navigation-elements] ```typescript 'example.com': [ 'nav *', 'header *', '.navigation', ] ``` ### Excluding Interactive UI [#excluding-interactive-ui] ```typescript 'example.com': [ 'button', 'input', 'select', '.modal', '.dropdown', ] ``` ### Excluding Technical Content [#excluding-technical-content] ```typescript 'example.com': [ 'pre', 'code', '.code-block', '.terminal', ] ``` ## Global DOM Rules [#global-dom-rules] In addition to custom rules, Read Frog has several global rules that apply to all websites: ### Force Block Tags [#force-block-tags] Elements that are always treated as block-level: ```typescript export const FORCE_BLOCK_TAGS = new Set([ "BODY", "H1", "H2", "H3", "H4", "H5", "H6", "BR", "FORM", "SELECT", "BUTTON", "LABEL", "UL", "OL", "LI", "BLOCKQUOTE", "PRE", "ARTICLE", "SECTION", "FIGURE", "FIGCAPTION", "HEADER", "FOOTER", "MAIN", "NAV", ]); ``` ### Don't Walk and Translate Tags [#dont-walk-and-translate-tags] Elements that are never traversed for translation: ```typescript export const DONT_WALK_AND_TRANSLATE_TAGS = new Set([ "HEAD", "TITLE", "HR", "INPUT", "TEXTAREA", "IMG", "VIDEO", "AUDIO", "CANVAS", "SOURCE", "TRACK", "META", "SCRIPT", "NOSCRIPT", "STYLE", "LINK", "PRE", "svg", ...MATH_TAGS, ]); ``` ## Troubleshooting [#troubleshooting] ### Rules Not Working [#rules-not-working] 1. **Check domain spelling** - Ensure the domain matches exactly 2. **Verify selector syntax** - Test selectors in browser DevTools console 3. **Clear cache** - Reload the extension and refresh the page 4. **Check selector specificity** - Element might be matched by a more specific rule ### Elements Still Being Translated [#elements-still-being-translated] 1. Check if the element is a child of an excluded element 2. Verify the selector targets the correct elements 3. Look for dynamic elements loaded after page load ### Translation Breaking Page Layout [#translation-breaking-page-layout] 1. Use force block rules sparingly 2. Test on multiple pages of the same website 3. Consider using `!translate` rules instead of force block ## Contributing Custom Rules [#contributing-custom-rules] If you've created rules that benefit others, consider contributing them: 1. Test thoroughly on multiple pages 2. Document why the rules are needed 3. Submit a Pull Request with your changes 4. Follow the [Contribution Guidelines](/docs/code-contribution/contribution-guide) See the [Code Contribution Guide](/docs/code-contribution/contribution-guide) for more details on submitting changes. # Configuration, Sync & Backups (/en/docs/configuration) Open **Options → Config** to move or recover settings. Interface language is configured separately under **Options → General**. ## Export safely [#export-safely] The export dialog lets you include or exclude provider API keys. Exclude keys for normal backups, bug reports, shared files, and version control. Include them only when moving your own configuration through storage you trust. An export containing API keys is a credential file. Anyone who obtains it may be able to spend your provider quota or access your account. ## Import and validation [#import-and-validation] Read Frog validates and migrates imported configuration before applying it. It also creates a backup of the current configuration first, so you can restore if the imported settings are valid but unsuitable. Importing replaces many current values. Review providers, target language, Site Control, and per-tool disabled websites afterward—especially when the file came from another browser profile. ## Google Drive manual sync [#google-drive-manual-sync] Connect Google Drive from the Config page, then start sync manually when you want to exchange settings with another browser. Google Drive sync controls in Read Frog settings If only one side changed, Read Frog can use the newer copy. If both local and remote values changed, the conflict dialog lets you choose local or remote values per field, or select all local/all remote before confirming. Choosing local or remote settings during a Google Drive conflict Validate the merged configuration in the dialog before applying it. Manual sync avoids silent background overwrites, but it also means changes do not appear on another device until you start sync there. ## Automatic and manual backups [#automatic-and-manual-backups] Read Frog checks for changed configuration about every 60 minutes and creates an automatic backup only when something changed. It keeps up to eight backups. You can also: * create a manual backup before an experiment; * restore a selected backup; * export a backup to a file; * delete backups you no longer need. Backups are local to the browser profile unless you export or sync them. Before editing large Site Rules or prompt sets, make a manual backup with a recognizable timestamp. ## Interface language [#interface-language] **Options → General → Interface Language** controls the Read Frog UI independently from the browser's display language. Changing it does not change translation source/target languages or website language detection. ## Beta Experience and reset [#beta-experience-and-reset] Beta Experience enables experimental features that explicitly depend on it. Text to Speech is labeled Public Beta but no longer requires this switch. Reset restores the default configuration. It is appropriate when a migrated or heavily edited setup cannot be repaired, but it removes customized providers, prompts, rules, and tool choices. Export without keys for support, and create a secure backup if you need credentials, before resetting. ## Recovery sequence [#recovery-sequence] When a configuration change causes a problem: 1. export the current state without API keys for inspection; 2. restore the most recent known-good local backup; 3. if necessary, import a trusted export; 4. reconnect Google Drive and resolve conflicts deliberately; 5. use Reset only after the earlier recovery paths fail. This order preserves the most evidence and gives you the easiest route back. # Custom AI Actions (/en/docs/custom-actions) ## Overview [#overview] Custom AI Actions turn a prompt into a small tool that you can run again and again. The core idea is simple. After you select text, Read Frog sends that text to AI with a fixed setup. Each action has: * an LLM provider * prompts * output fields This is different from a normal chat box. The result is more stable. It works well for repeated reading tasks, such as dictionary lookup, explanation, rewriting, and summaries. Before you use this feature, make sure you have enabled at least one LLM provider that supports structured output and can connect successfully. If you are not sure whether your model supports structured output, check [AI SDK Model Capabilities](https://ai-sdk.dev/docs/foundations/providers-and-models#model-capabilities) or the model provider's official docs. ## Built-in AI Actions [#built-in-ai-actions] The current version includes three templates: * **Dictionary**: look up a word and return the term, phonetic, part of speech, definition, paragraph text, paragraph translation, and CEFR difficulty * **Improve Writing**: analyze writing problems and return an improved version * **Blank**: start from scratch Notes: * The Custom AI Actions page already includes a default **Dictionary** action. You can study it to learn how prompts and output fields are designed. * If you want a writing helper, click **Add AI Action** and choose **Improve Writing**. ## Learn from the Built-in Dictionary [#learn-from-the-built-in-dictionary] If this is your first time using the feature, start with the built-in dictionary. 1. Set up and enable an LLM provider for reading tasks. 2. Open **Custom AI Actions** and make sure **Dictionary** is enabled. 3. If its provider is not available, switch it to an enabled LLM provider. 4. Go back to any webpage and select a word or a short phrase. 5. Click the dictionary icon in the selection toolbar. Dictionary in the selection toolbar You will see structured results like these: ```markdown - Term - Phonetic - Part of Speech - Definition - Paragraphs - Paragraphs Translation - Difficulty ``` ## Customize Your Own AI Action [#customize-your-own-ai-action] 1. Open Read Frog settings. 2. Go to **Custom AI Actions**. 3. Click **Add AI Action**. 4. Choose a template: **Dictionary**, **Improve Writing**, or **Blank**. 5. Fill in the required fields. 6. Keep the action enabled so it appears in the selection toolbar. The editor supports these fields: * **Name**: the action name * **Icon**: you can search for icons on [icon-sets.iconify.design](https://icon-sets.iconify.design/) and copy the icon name * **Provider**: choose an LLM provider that supports structured output * **System Prompt**: define the role, goal, rules, and examples * **Prompt**: define the input format and explain what the model receives * **Output Schema**: define the structured fields in the result ## Prompt Tokens [#prompt-tokens] Both the system prompt and the main prompt support these tokens: * `{{selection}}`: the selected text * `{{paragraphs}}`: the paragraphs around the selection, joined with blank lines, up to 2000 characters * `{{targetLanguage}}`: the user's target language * `{{webTitle}}`: the page title ## How Output Schema Works [#how-output-schema-works] Each output field includes: * **Field Name** * **Field Type**: `string` or `number` * **Field Description** * **Enable speaking**: the panel shows a speak button, and the user can read this field aloud Notes: * The speaking feature depends on the Text-to-Speech feature. * Make sure the voice language is correct, or playback may fail. The output schema has two jobs: 1. It tells the model which fields must be returned. 2. It tells Read Frog how to show the result. The field description is also important. It is not only a note for humans. It is passed into the structured output rules too. You can use it to define language, length, format, and other constraints. ## Save Results to Notebase [#save-results-to-notebase] When you are logged in, you can use the **Notebase Connection** section while editing an AI action. For the full version check, Notebase setup, field mapping, and testing flow, see the [Notebase Guide](/docs/notebase-beta). Notebase field mapping Here you can: 1. choose a notebase 2. map AI action fields to notebase fields 3. save structured results from the selection panel Save to Notebase This is very useful if you want to turn dictionary results into your own vocabulary list. > In the future, these saved words support review with the FSRS algorithm. ## Build One: Reading Summary Action [#build-one-reading-summary-action] If you want to build your first custom action, start with **Blank** and make a reading summary tool. Summary action demo ### System Prompt [#system-prompt] ```text You are a summary assistant for learners and researchers. ## Goal Read the given article content and produce a clear and accurate summary that matches the required output object. ## Rules 1. Only use information from the given content. Do not add new facts. 2. Focus on the main topic, the core summary, the key points, and important details. 3. Stay faithful to the original meaning. 4. Use clear and simple language that is good for reading and review. 5. Do not rewrite the full text line by line. Extract information instead. 6. Keep important technical or academic terms when needed. 7. Important details should help the reader understand the text better. 8. If a field cannot be determined from the text, return an empty string. 9. Use {{targetLanguage}} for every field except original source content. 10. Keep the output tightly related to the input text. ## Examples ### Example 1 Input: Selection: hybrid models Paragraphs: Remote work has changed how companies operate. It gives employees more flexibility, reduces commuting time, and can improve work-life balance. However, it also creates challenges in communication, team cohesion, and performance management. Many companies are now trying hybrid models to balance flexibility and collaboration. Target language: English Output: - Topic: The impact of remote work on companies and employees - Summary: The text explains that remote work brings flexibility and efficiency benefits, but it also creates problems in communication, team cohesion, and performance management, so many companies now use hybrid work as a practical balance. - Key Points: 1. Remote work gives employees more flexibility.\r\n 2. Remote work reduces commuting time.\r\n 3. Remote work can improve work-life balance.\r\n 4. Remote work can cause communication and teamwork problems.\r\n 5. Hybrid work is a common way to balance flexibility and collaboration.\r\n - Details: 1. The text covers both employee benefits and management challenges.\r\n 2. The main problems are communication, team cohesion, and performance management.\r\n 3. Hybrid work is presented as a practical solution, not just a theory.\r\n ### Example 2 Input: Selection: 誤分類が依然として多かった Paragraphs: この論文では、画像認識における小規模データ問題を解決するために、事前学習済みモデルの転移学習を活用した。実験の結果、少量データ環境でも高い精度が得られたが、特定のカテゴリでは誤分類が依然として多かった。今後はデータ拡張とモデル軽量化が課題である。 Target language: English Output: - Topic: The effect of transfer learning on small-scale image recognition - Summary: The text explains that transfer learning with a pre-trained model helps improve image recognition in small-data settings, but some categories still have many misclassifications, so data augmentation and model compression remain important future tasks. - Key Points: 1. The study aims to solve the small-data problem in image recognition.\r\n 2. It uses transfer learning with a pre-trained model.\r\n 3. The results show high accuracy even with limited data.\r\n 4. Some categories still have clear misclassification problems.\r\n 5. Future work includes data augmentation and model compression.\r\n - Details: 1. The method is effective specifically in low-data settings.\r\n 2. The results are not equally stable across all categories.\r\n 3. The text clearly gives future improvement directions instead of only reporting results.\r\n ``` ### Prompt [#prompt] ```text Selection: {{selection}} Paragraphs: {{paragraphs}} Target language: {{targetLanguage}} ``` ### Output Schema [#output-schema] | Field Name | Field Type | Description | | ---------- | ---------- | -------------------------------------------------------------------------------------------- | | Topic | Text | Summarize the core topic related to `{{selection}}`. | | Summary | Text | Explain the core meaning of `{{selection}}` in one sentence. | | Key Points | Text | Extract the 3 to 5 most relevant points related to `{{selection}}`, separated by `\r\n`. | | Details | Text | List important details that are easy to miss but help the reader understand `{{selection}}`. | This gives you a reusable reading helper for articles, docs, and tutorials. ## Practical Tips [#practical-tips] * Start with fewer fields. Fewer fields usually means more stable results. * Use the **System Prompt** to guide the model and give examples. * Use the **Prompt** to define the current input format. * If the result is unstable, remove fields and simplify the rules first. * For dictionary use, select a word or a short phrase, not a full sentence. ## Troubleshooting [#troubleshooting] ### The AI action exists but does not run [#the-ai-action-exists-but-does-not-run] First check whether the provider for this action is enabled and whether the model supports structured output. ### I do not see the Save to Notebase button [#i-do-not-see-the-save-to-notebase-button] Make sure you are logged in to the same account on readfrog.app, the extension is up to date, and the AI action has a valid **Notebase Connection**. # Custom Translation Styles (/en/docs/custom-css) ## Overview [#overview] Read Frog allows you to customize how translations appear on webpages using your own CSS styles. This gives you complete control over colors, backgrounds, borders, animations, and more. You can apply styles globally to all translations, or target specific languages and text directions. For example, you can use different fonts for Chinese, Japanese, and Korean translations, or adjust layout for right-to-left languages like Arabic and Hebrew. ## Enabling Custom CSS [#enabling-custom-css] 1. Open Read Frog settings 2. Navigate to **Translation** → **Translation Display Style** 3. Toggle **"Use Custom Style"** to ON 4. The CSS editor will appear with a default template ## CSS Selectors [#css-selectors] ### Basic Selector [#basic-selector] All custom styles must target the specific selector: ```css [data-read-frog-custom-translation-style="custom"] { /* Your styles here */ } ``` This selector applies to all translated text elements on the page. ### Wrapper Selector [#wrapper-selector] Translated content is wrapped in a container with language and direction attributes: ```html 神谷先生... ``` You can target specific languages or directions: ```css /* Target Chinese translations */ .read-frog-translated-content-wrapper[lang="zh"] [data-read-frog-custom-translation-style="custom"] { /* Styles for Chinese */ } /* Target RTL languages */ .read-frog-translated-content-wrapper[dir="rtl"] [data-read-frog-custom-translation-style="custom"] { /* Styles for right-to-left text */ } ``` ## Editor Features [#editor-features] ### Syntax Highlighting [#syntax-highlighting] The editor uses CodeMirror 6, providing: * Color-coded CSS syntax * Line numbers * Code folding for large stylesheets * Auto-indentation ### Color Picker [#color-picker] Click any color value in the editor to open an interactive color picker: 1. Click on color values like `#FF5733`, `rgb(255, 87, 51)`, or `hsl(9, 100%, 60%)` 2. Visual picker appears instantly 3. Adjust using sliders or input fields 4. Changes update in real-time Supported color formats: * Hex: `#FF5733` * RGB/RGBA: `rgba(255, 87, 51, 0.8)` * HSL/HSLA: `hsla(9, 100%, 60%, 0.8)` * Named colors: `tomato`, `skyblue`, `gold` * CSS variables: `var(--my-color)` ### Live Validation [#live-validation] The editor validates your CSS before saving: * **Valid (Green)**: CSS is syntactically correct, ready to save * **Validating (Gray)**: Checking your changes (500ms debounce) * **Error (Red)**: Syntax error detected with error message Validation checks: * Syntax errors (typos, missing brackets) * Property name validity * Selector correctness * Size limits (8KB maximum) ## Basic CSS Examples [#basic-css-examples] ### Simple Font Color [#simple-font-color] ```css [data-read-frog-custom-translation-style="custom"] { color: blue; } ``` ### With Border [#with-border] ```css [data-read-frog-custom-translation-style="custom"] { color: #414535; background-color: #f2e3bc; padding: 2px 4px; border-radius: 4px; border-left: 3px solid #ffd700; } ``` ### Bold Study Mode [#bold-study-mode] ```css [data-read-frog-custom-translation-style="custom"] { background-color: #fff59d; color: #000; font-weight: 600; border: 2px solid #ffd54f; padding: 6px 10px; border-radius: 4px; } ``` ## Advanced Techniques [#advanced-techniques] ### Custom Fonts [#custom-fonts] Change the font for all translations: ```css [data-read-frog-custom-translation-style="custom"] { font-family: "Georgia", "Times New Roman", serif; font-size: 16px; color: #2c3e50; } ``` ### Language-Specific Styling [#language-specific-styling] Target translations in specific languages using the wrapper's `lang` attribute: ```css /* Chinese translations with traditional serif font */ .read-frog-translated-content-wrapper[lang="zh"] [data-read-frog-custom-translation-style="custom"] { font-family: "Kaiti SC", "STKaiti", "KaiTi", "华文楷体", serif; color: #8b4513; } /* Japanese translations */ .read-frog-translated-content-wrapper[lang="ja"] [data-read-frog-custom-translation-style="custom"] { font-family: "Hiragino Mincho ProN", "Yu Mincho", serif; } /* Korean translations */ .read-frog-translated-content-wrapper[lang="ko"] [data-read-frog-custom-translation-style="custom"] { font-family: "Nanum Myeongjo", "Batang", serif; } ``` ### Direction-Specific Styling [#direction-specific-styling] Style translations based on text direction (useful for RTL languages like Arabic, Hebrew): ```css /* Right-to-left languages */ .read-frog-translated-content-wrapper[dir="rtl"] [data-read-frog-custom-translation-style="custom"] { border-right: 3px solid #9c27b0; border-left: none; padding-right: 10px; font-family: "Traditional Arabic", "Arial", sans-serif; font-size: 15px; } /* Left-to-right languages */ .read-frog-translated-content-wrapper[dir="ltr"] [data-read-frog-custom-translation-style="custom"] { border-left: 3px solid #2196f3; padding-left: 10px; } ``` ### CSS Variables [#css-variables] Define reusable values: ```css [data-read-frog-custom-translation-style="custom"] { --highlight-color: #ffe082; --border-color: #ffa726; background-color: var(--highlight-color); border-left: 4px solid var(--border-color); padding: 4px 10px; } ``` ### Light/Dark Mode Support [#lightdark-mode-support] Use `light-dark()` function for automatic theme adaptation: ```css [data-read-frog-custom-translation-style="custom"] { background-color: light-dark(#fff9c4, #4a4a2a); color: light-dark(#333, #e0e0e0); border: 1px solid light-dark(#ffd54f, #8d7b3a); padding: 5px 10px; border-radius: 4px; } ``` ### Hover Effects [#hover-effects] ```css [data-read-frog-custom-translation-style="custom"] { color: #0277bd; transition: color 0.2s ease-out, transform 0.2s ease-out; } [data-read-frog-custom-translation-style="custom"]:hover { color: #01579b; transform: translateX(2px); } ``` ### Animations [#animations] ```css [data-read-frog-custom-translation-style="custom"] { background: linear-gradient(90deg, #1fe5e1 0%, #a855f7 50%, #0ad6ff 100%); background-size: 200% 100%; -webkit-background-clip: text; background-clip: text; -webkit-text-fill-color: transparent; animation: gradient-shift 2s ease-in-out infinite; } @keyframes gradient-shift { 0%, 100% { background-position: 0% 50%; } 50% { background-position: 100% 50%; } } ``` ## Best Practices [#best-practices] ### Do's ✅ [#dos-] * Start with simple styles and add complexity gradually * Test on multiple websites * Use low-opacity backgrounds to maintain readability * Include units for length values: `padding: 10px` not `padding: 10` * Use complete hex codes: `#FF5733` not `#FF` ### Don'ts ❌ [#donts-] * Avoid `!important` (selector specificity is already high) * Don't write overly complex styles (focus on essential properties) * Don't exceed 8KB size limit * Avoid missing units or incomplete color codes ## Common Properties [#common-properties] | Property | Purpose | Example | | ------------------ | ---------------- | ---------------------------------- | | `color` | Text color | `color: #333;` | | `background-color` | Background color | `background-color: #FFF59D;` | | `padding` | Inner spacing | `padding: 4px 8px;` | | `border` | Border style | `border: 1px solid #FFD54F;` | | `border-radius` | Rounded corners | `border-radius: 4px;` | | `font-weight` | Text boldness | `font-weight: 600;` | | `font-size` | Text size | `font-size: 14px;` | | `text-decoration` | Underline, etc. | `text-decoration: underline;` | | `opacity` | Transparency | `opacity: 0.8;` | | `transition` | Animation timing | `transition: color 0.2s ease-out;` | ## Technical Limitations [#technical-limitations] * **Maximum size**: 8KB (8,192 characters) * **Editor**: CodeMirror 6 * **Validation**: CSS Tree parser * **Selector**: Must use `[data-read-frog-custom-translation-style='custom']` * **Wrapper class**: Translations are wrapped in `.read-frog-translated-content-wrapper` with `lang` and `dir` attributes * **Available attributes**: `lang` (ISO 639-1 language codes) and `dir` (ltr/rtl) ## Learning CSS [#learning-css] If you're new to CSS, these resources will help: ### Beginner Tutorials [#beginner-tutorials] * [MDN CSS Basics](https://developer.mozilla.org/en-US/docs/Learn/CSS/First_steps) - Comprehensive introduction * [W3Schools CSS Tutorial](https://www.w3schools.com/css/) - Interactive examples * [CSS-Tricks Guides](https://css-tricks.com/guides/) - Practical CSS techniques ### CSS Properties Reference [#css-properties-reference] * [MDN CSS Reference](https://developer.mozilla.org/en-US/docs/Web/CSS/Reference) - Complete property documentation * [CSS Values and Units](https://developer.mozilla.org/en-US/docs/Learn/CSS/Building_blocks/Values_and_units) - Understanding units (px, %, em, etc.) ### Colors [#colors] * [MDN Color Values](https://developer.mozilla.org/en-US/docs/Web/CSS/color_value) - Color formats explained * [Coolors](https://coolors.co/) - Color palette generator * [Color Hunt](https://colorhunt.co/) - Color scheme inspiration ### Interactive Practice [#interactive-practice] * [CSS Diner](https://flukeout.github.io/) - Learn CSS selectors through games * [Flexbox Froggy](https://flexboxfroggy.com/) - Learn layout (though not needed for basic styling) ## Troubleshooting [#troubleshooting] ### Style Not Applying [#style-not-applying] 1. Check validation status (must be green "Valid") 2. Verify selector is exactly `[data-read-frog-custom-translation-style='custom']` 3. Ensure "Use Custom Style" is toggled ON 4. Refresh the webpage after saving ### Syntax Errors [#syntax-errors] Common mistakes: * Missing semicolon: `color: red` → `color: red;` * Missing unit: `padding: 10` → `padding: 10px` * Incomplete color: `#FF` → `#FF5733` * Invalid property: `colour: red` → `color: red` ### Style Conflicts [#style-conflicts] If styles look unexpected: * Check if website's CSS is overriding yours * Increase specificity if needed (though usually not required) * Test on different websites to identify site-specific issues # Future Plan (/en/docs/future-plan) | Status | Feature | Description | | :----: | --------------- | ----------------------------------------------------------------------- | | ✅ | Support more AI | Already supports over 20 AI providers | | ✅ | Select Content | Translate user-selected content | | 🚧 | Vocabulary | Vocabulary review system | | | Auto Review | Auto-review words from vocabulary list when they appear in new webpages | | 🚧 | Word Highlight | Highlight difficult words in the original webpage | | | Voice Guide | Article explanation with voice like a real teacher | | | Mobile | Mobile support | | | Multi-modal | Multi-modal understanding of images and charts in articles | 1. ✅: Done; Reviewing means waiting for approval from the store 2. 🚧: In Progress If you want to submit a feature suggestion, please raise it in [Github Issues](https://github.com/mengxi-ream/read-frog/issues), or email it to `support@readfrog.app`. # Introduction (/en/docs) ## Read Frog [#read-frog] Read Frog is an open-source browser extension for reading in another language. Translate pages bilingually or in translation-only mode, translate a selected paragraph, listen with Text-to-Speech, create reusable Custom AI Actions, and turn useful results into Notebase study material. Start with [Installation](/docs/installation), then choose a provider in [Set Up Providers and API Keys](/docs/api-key). See [Page and Paragraph Translation](/docs/translation) for everyday reading, [Advanced Translation Settings](/docs/advanced-translation) for rate and batching controls, and [Video Subtitles](/docs/video-subtitles) for YouTube. ## Open source and community [#open-source-and-community] Read Frog is open source. Report bugs, share site rules, and contribute improvements on GitHub. Join the [Discord](https://discord.gg/ej45e3PezJ) community for help and discussion. # Installation (/en/docs/installation) ## Install the extension [#install-the-extension] Install Read Frog from the [Chrome Web Store](https://chromewebstore.google.com/detail/read-frog/modkelfkcfjpgbfmnbnllalkiogfofhb?utm_source=official) or [Microsoft Edge Add-ons](https://microsoftedge.microsoft.com/addons/detail/read-frog-open-source-a/cbcbomlgikfbdnoaohcjfledcoklcjbo). ## Choose a provider [#choose-a-provider] Open the extension popup and choose **Options**, then add an enabled translation provider in **API Providers**. Free translation providers and LLM providers have different capabilities; see [Set Up Providers and API Keys](/docs/api-key) before adding an API key. ## Make your first translation [#make-your-first-translation] Open a page in a language you want to read, set source and target languages in the popup or options, and use the floating button or popup **Translate** action. Use the selection toolbar for a single phrase or paragraph. You can later choose bilingual versus translation-only display and tune automatic translation in [Advanced Translation Settings](/docs/advanced-translation). # Translate Local Web Pages (/en/docs/local-files) ## Before you start [#before-you-start] Chrome and Edge do not allow extensions to access `file://` pages by default. This is a browser-controlled permission, so Read Frog cannot enable it automatically during installation. You only need to enable it once; the browser remembers your choice until you turn it off or remove the extension. ## Enable access to local files [#enable-access-to-local-files] **Open Read Frog's extension details** Right-click the Read Frog icon in the browser toolbar and select **Manage extension**. If the icon is not visible, open the Extensions menu first. You can also enter `chrome://extensions` in Chrome or `edge://extensions` in Edge, find Read Frog, and select **Details**. Browser settings URLs must be typed or pasted into the address bar. **Turn on file URL access** Enable **Allow access to file URLs**. You do not need to turn on Developer mode. Read Frog extension details with the Allow access to file URLs setting highlighted **Reload the local page** Return to the local page and reload it so Read Frog can run on the page. ## Translate a local HTML file [#translate-a-local-html-file] Open an `.html` or `.htm` file in the browser by dragging it into a tab or using **Ctrl+O** on Windows/Linux or **Command+O** on macOS. When the address starts with `file://`, use Read Frog's floating button, popup **Translate** action, or page shortcut as usual. This guide applies to HTML pages loaded from `file://`. Browser-internal pages such as `chrome://` and `edge://` pages cannot be translated by extensions. For translation modes and controls, see [Page and Paragraph Translation](/docs/translation). ## Alternative: serve the folder locally [#alternative-serve-the-folder-locally] If you prefer not to grant file URL access, serve the folder over HTTP and open the page from `localhost`. For example, run this command inside the folder if Python 3 is installed: ```bash python3 -m http.server 8000 ``` Then open `http://localhost:8000` in the browser. Tools such as VS Code Live Server provide the same kind of local address. Local pages can contain private information. Their text is processed according to your configured translation provider. Check your provider settings before translating sensitive files. ## Troubleshooting [#troubleshooting] * If Read Frog does not appear or respond, confirm that **Allow access to file URLs** is enabled, then reload the page. * If the address does not begin with `file://` or `http://localhost`, confirm that the file was opened in the browser. * If the page itself cannot load scripts, fonts, or other files, use a local HTTP server to avoid browser restrictions on local resources. # Connect an AI Assistant with MCP (/en/docs/mcp) Read Frog's MCP connection lets an AI assistant work with your learning workspace. You can save a word from a conversation, turn material you provide to the assistant into notes, or ask about your flashcards and study progress. ## Requirements [#requirements] * A Read Frog account with an active Ultra entitlement. See our [pricing page](/en/pricing) for plan details. * An AI assistant that supports remote MCP connections and OAuth. The connection uses this shared server address: ```text https://api.readfrog.app/api/mcp ``` ## Connect [#connect] Open the assistant's settings for custom connectors or remote MCP servers and add the address above. Choose OAuth if an authentication option is shown. Sign in to Read Frog, check the requesting application, choose the permissions you want to grant, and select **Allow**. In ChatGPT, custom MCP connections use developer mode where available. In Claude, use **Settings → Connectors → Add custom connector** where available. Your plan or workspace administrator may control access to these settings. A custom connection can be used before a public directory listing is available. You do not need to give the assistant your Read Frog password or a manually copied access token. Complete sign-in on Read Frog's authorization page. ## Choose permissions [#choose-permissions] Read Frog groups permissions into account information, notebases and fields, note content, card templates, and study activity. Account access is read-only. Each other group can be denied, read-only, or read/write when requested by the client. Reading rendered cards requires both note and study read permissions. Write permissions include the corresponding creation, changes, and deletions. Deleting a notebase, field, note, or card template can also remove related content. Review the requested changes before approving destructive actions in your assistant. ## Try these workflows [#try-these-workflows] ### Save a word from a conversation [#save-a-word-from-a-conversation] > Save the English word we just discussed as note The assistant should identify the word, inspect your notebase's fields, and save the note in the format that notebase uses. If several destinations fit, tell it which notebase to use. ### Create notes from learning material [#create-notes-from-learning-material] > Turn the PDF or webpage I provide into structured learning notes and save them to my notebase. Upload a PDF or provide accessible webpage content to your assistant. The assistant reads the source with its own file or web capabilities; Read Frog MCP saves the resulting notes. If your assistant cannot access a source, provide its text directly. Read Frog's MCP tools do not fetch arbitrary URLs or parse PDFs. ### Plan a review [#plan-a-review] > What should I review today? The assistant can inspect study counts and card content, due dates, and scheduling states. Make sure it knows your timezone. Large collections may require multiple pages of results, and your daily limits affect the in-app study plan. There is no dedicated MCP review-queue tool, so a list of due cards should not be presented as an exact copy of the app's review order. ## Manage and disconnect [#manage-and-disconnect] Open [MCP settings](https://www.readfrog.app/mcp) in Read Frog to view connected applications and revoke a connection. You can also remove the connector in your assistant. Revoking access does not erase content already received by that service. See our [Privacy Policy](/privacy-policy) for data handling details. ## Troubleshooting [#troubleshooting] * **A tool needs more permissions:** authorize the requested permission in Read Frog, or keep it denied and use only the operations you allowed. Some clients require reconnecting manually to request additional permissions. * **The connection works but a tool reports a plan restriction:** the account needs an eligible Ultra entitlement. Signing in again does not change its plan. * **New tools are missing:** refresh or reconnect the custom connector. Published directory entries may need a separately reviewed metadata update. * **A note changed before your edit:** ask the assistant to read its latest value before trying the update again. For help, contact [Read Frog support](https://www.readfrog.app/contact). # Notebase Guide (/en/docs/notebase-beta) ## Before You Start [#before-you-start] Notebase is available to all logged-in users. We will continue improving the interaction details, naming, sync behavior, and error messages as the workflow evolves. If you run into a problem or want us to improve a workflow, please open feedback in [GitHub Issues](https://github.com/mengxi-ream/read-frog/issues). When you file an issue, include your extension version, browser, steps to reproduce, and screenshots when possible. Keep the Read Frog extension up to date before configuring Notebase. Browser-store installs update automatically; manually installed builds must be updated from [GitHub Releases](https://github.com/mengxi-ream/read-frog/releases). ## Requirements [#requirements] Please check these requirements first: 1. You are logged in to [readfrog.app](https://readfrog.app). 2. Your Read Frog extension is up to date. 3. The extension and readfrog.app use the same account when saving selected-text results. ## 1. Create a Notebase [#1-create-a-notebase] Open [readfrog.app/home](https://readfrog.app/home) to enter the workspace home page. **Create a Notebase** Click **Create Notebase**, enter a name such as "Reading Notes" or "Vocabulary", and click **Create**. The Create Notebase button on the readfrog.app workspace home page **Add fields** After opening the Notebase, click **Add column** and add the fields you want to save. Common fields include: * Term * Definition * Example sentence * Paragraph translation * Difficulty The Add column control in the Notebase detail page **Add one note manually** Click **Add note** or **New note**, manually enter one test row, and confirm that this Notebase can be edited and synced. The Add note control in the Notebase detail page ## 2. Configure Save to Notebase [#2-configure-save-to-notebase] The Notebase save entry point lives in the extension's **Custom AI Actions**. First make an AI action produce structured output, then map those output fields to Notebase fields. **Open Custom AI Actions** Open the extension options page and go to **Custom AI Actions**. Open Custom AI Actions **Choose or create an action** You can start with the default dictionary action or create a new action. Make sure the action is enabled and uses an LLM provider that supports structured output. Dictionary Action **Configure output fields** In **Output Schema**, check the field names and field types. Notebase can only save fields that are mapped. Connect Notebase Schema **Configure the Notebase connection** Find **Notebase Connection** in the action editor: 1. Select the Notebase you created. 2. Click **Add mapping**. 3. Map each "action field" to the matching "Notebase field". 4. Save the Custom AI Action. Notebase Connection configuration Field types must match. For example, text output should map to a text field, and number output should map to a number field. If a field is deleted or its type changes, the mapping becomes invalid and needs to be refreshed and fixed. ## 3. Test Saving Results [#3-test-saving-results] **Select text on a webpage** Open any webpage and select a word, phrase, or short passage. Select Text **Run the Custom AI Action** Click the Custom AI Action you configured in the selection toolbar and wait for the structured result. Structured Result Panel **Save to Notebase** Click **Save to Notebase** in the result panel. If the save succeeds, you will see a success notification. Save to Notebase **Check the Notebase** Go back to the Notebase page on readfrog.app and confirm that the saved content appears in your notes. Check Notebase ## 4. Add a Card Template [#4-add-a-card-template] A Card Template turns each note in a Notebase into a reviewable card. The template decides what appears on the card front and what appears on the card back. Card Template Example **Open Templates & Cards** Open a Notebase and switch to the **Templates & Cards** tab. **Click Add template** Click **Add template** to open the template editor. Add Card Template **Name the template** In **Name**, enter a template name such as "Word definition", "Question answer", or "Concept review". **Configure Front and Back** Put the content you want to see first in **Front**, and put the answer content in **Back**. You can click field buttons to insert Notebase fields into the template. For example, if your Notebase is a vocabulary list: * **Front**: term, example sentence, or question * **Back**: definition, paragraph translation, usage notes, or answer If your Notebase stores other knowledge, configure the card around that knowledge structure: * **Front**: question, concept name, formula, or historical event * **Back**: answer, explanation, derivation, or background information Configure Card Template **Save and check Cards** After saving, the **Cards** section shows card previews generated from your notes and template. Card Preview ## 5. Start Reviewing [#5-start-reviewing] What you review depends on the notes saved in your Notebase and how the Card Template is configured. It can be English vocabulary and sentences, or any other knowledge you store in Notebase. **Click Review** Open the Notebase detail page and click **Review** in the top-right corner. Review Button **Read the Front first** The review page shows the card **Front** first. Try to recall the answer before revealing it. Review Front **Click Reveal Answer** Click **Reveal Answer** to show the **Back**. Review Back **Choose a review result** Choose **Again**, **Hard**, **Good**, or **Easy** based on how well you remembered the card. The system schedules future reviews based on your choice. Review Buttons If the page shows **Done for today**, there are no cards due for the current study day. Come back later, or first check that you have created notes and a Card Template. ## Troubleshooting [#troubleshooting] ### I do not see the Save to Notebase button [#i-do-not-see-the-save-to-notebase-button] Check these items in order: 1. Is the extension up to date? 2. Are you logged in to the same account on readfrog.app? 3. Does this Custom AI Action have a **Notebase Connection**? 4. Are the field mappings valid? ### My extension is out of date [#my-extension-is-out-of-date] Update the extension, reopen it, and retry. Browser-store installs update automatically; manually installed builds must be updated from [GitHub Releases](https://github.com/mengxi-ream/read-frog/releases). ### The mapping is invalid or the save button is disabled [#the-mapping-is-invalid-or-the-save-button-is-disabled] If you changed Notebase fields or deleted output fields from the Custom AI Action, the old mapping may become invalid. Go back to **Custom AI Actions → Notebase Connection**, refresh the schema, and select the field mappings again. ### I see a login required message [#i-see-a-login-required-message] Log in on [readfrog.app](https://readfrog.app) first. The extension and the web app need to use the same account to save selected-text results into your Notebase. ### The selected Notebase is unavailable [#the-selected-notebase-is-unavailable] This usually means the Notebase was deleted, account access changed, or sync temporarily failed. Refresh the Notebase list first. If it still does not recover, select another Notebase and fix the mappings. ### No cards are generated in Templates & Cards [#no-cards-are-generated-in-templates--cards] Make sure this Notebase has notes and at least one Card Template. If you just added a note or template, wait for sync to finish and then refresh. ### The review page says Done for today [#the-review-page-says-done-for-today] This means there are no cards due for the current study day. It does not always mean something is misconfigured. If you have not created a Card Template or the Notebase has no notes yet, add those first. ## Feedback [#feedback] The goal of Notebase feedback is to find real workflow problems quickly. You can report: * which step is unclear * which button or entry point is hard to find * whether saving is stable * whether field mapping is flexible enough * whether Card Templates are easy to configure * whether the review flow fits your learning scenario * which field types or review flows you want Notebase to support Please submit feedback in [GitHub Issues](https://github.com/mengxi-ream/read-frog/issues). We will keep improving Notebase quickly during the beta period. # Built-in Provider Configuration (/en/docs/providers/built-in-providers) ## Add a built-in provider [#add-a-built-in-provider] Open **Options → API Providers**, choose **Add Provider**, select a built-in provider, enter its API key when required, choose a model if the provider exposes one, and enable it. Use **Test Connection** before selecting the provider for translation, subtitles, or an AI feature. Translation providers such as Google Translate, Microsoft Translate, DeepL, and DeepLX are suitable for translation features. LLM providers also support AI Smart Context, custom prompts, subtitle AI segmentation, and Custom AI Actions. Custom AI Actions and Notebase structured results require a model with reliable structured output. ## Keep configuration current [#keep-configuration-current] Provider catalogs, model IDs, quota policies, and supported options change often. Select models from the extension UI or fetch them from a provider when that control is available; do not rely on a documentation list of default models. Use the provider's official documentation for pricing, regions, quotas, and API-key creation. If a response is malformed, test the connection, confirm the selected model and API key, and review provider-specific options. Disable reasoning output when the provider exposes it and the model adds reasoning text before a structured response. # DeepL (/en/docs/providers/deepl) ## What is DeepL? [#what-is-deepl] DeepL is the official paid translation API from DeepL. In Read Frog, it is separate from DeepLX: * **DeepL** uses DeepL's official API and requires a valid DeepL API key. * **DeepLX** is an unofficial DeepL-like API with customizable Base URL behavior. If you want the official DeepL service, choose **DeepL** in the API Providers page. ## How Read Frog Configures DeepL [#how-read-frog-configures-deepl] DeepL setup in Read Frog is intentionally simple: * **API Key**: required * **Base URL**: not shown and not configurable Read Frog decides the correct DeepL endpoint from your API key automatically: * Keys ending with `:fx` use `https://api-free.deepl.com` * All other keys use `https://api.deepl.com` You do not need to manually choose between Free and Pro endpoints. ## Setting Up DeepL in Read Frog [#setting-up-deepl-in-read-frog] 1. Open the Read Frog extension options. 2. Go to **API Providers**. 3. Select **Official DeepL API**. 4. Paste your DeepL API key into the **API Key** field. 5. Test a translation. That is all you need. There is no Base URL field for DeepL. ## Free vs Pro DeepL Keys [#free-vs-pro-deepl-keys] Read Frog uses the API key format to decide which DeepL endpoint to call. ### DeepL Free [#deepl-free] If your key ends with `:fx`, Read Frog sends requests to: ```text https://api-free.deepl.com/v2/translate ``` ### DeepL Pro [#deepl-pro] If your key does not end with `:fx`, Read Frog sends requests to: ```text https://api.deepl.com/v2/translate ``` ## Language Handling [#language-handling] Read Frog adapts some language codes automatically for DeepL: * Target `zh` becomes `ZH-HANS` * Target `zh-TW` becomes `ZH-HANT` * Source `zh-TW` is normalized to `ZH` * When source language is set to `auto`, Read Frog lets DeepL detect it automatically ## Troubleshooting [#troubleshooting] ### "DeepL API key is not configured" [#deepl-api-key-is-not-configured] Your API key field is empty. Add a valid DeepL API key in the provider settings. ### "DeepL translation request failed" [#deepl-translation-request-failed] Usually this means one of the following: * The API key is invalid * The API key type does not match your DeepL plan * The DeepL service rejected the request ### Free key not working [#free-key-not-working] Make sure your DeepL Free key still ends with `:fx`. Read Frog uses that suffix to select the Free API endpoint. ## When to Use DeepL vs DeepLX [#when-to-use-deepl-vs-deeplx] Choose **DeepL** if you want: * The official DeepL API * Automatic Free/Pro endpoint handling * A simpler setup with only an API key Choose **DeepLX** if you want: * A custom or self-hosted DeepLX provider * Custom Base URL patterns * `{{apiKey}}` placeholder support inside the URL # DeepLX (/en/docs/providers/deeplx) ## What is DeepLX? [#what-is-deeplx] DeepLX is a free, unofficial API that provides DeepL-like translation quality through reverse engineering. It offers an alternative to the official DeepL API for developers who need high-quality translation services without the cost. ## Flexible BaseURL Configuration [#flexible-baseurl-configuration] Read Frog supports flexible DeepLX baseURL configuration to work with different DeepLX providers. You can customize the baseURL to match your provider's specific endpoint format. ### Token Placeholder Support [#token-placeholder-support] You can use the `{{apiKey}}` placeholder in your baseURL to insert your API token at any position. This is useful when different DeepLX providers require tokens in different URL formats. **Examples:** 1. **Token in path**: `https://api.deeplx.com/{{apiKey}}/translate` 2. **Token as query parameter**: `https://api.deeplx.com/v1/translate?token={{apiKey}}` 3. **Token in subdomain**: `https://{{apiKey}}.api.deeplx.com/translate` ### Special URL Handling [#special-url-handling] #### Standard DeepLX URLs [#standard-deeplx-urls] For most DeepLX providers, if your baseURL doesn't end with `/translate`, Read Frog will automatically append it: * **Input**: `https://deeplx.example.com` * **Output**: `https://deeplx.example.com/translate` With API token: * **Input**: `https://deeplx.example.com` + token `abc123` * **Output**: `https://deeplx.example.com/abc123/translate` #### api.deeplx.org Special Logic [#apideeplxorg-special-logic] For the official `https://api.deeplx.org` endpoint, Read Frog applies special logic to insert the API token between `.org` and `/translate`: * **Without token**: `https://api.deeplx.org/translate` * **With token**: `https://api.deeplx.org/your-token/translate` ### Configuration Examples [#configuration-examples] #### No API Token Required [#no-api-token-required] Some DeepLX providers don't require authentication: ``` BaseURL: https://deeplx.vercel.app API Key: (leave empty) Result: https://deeplx.vercel.app/translate ``` #### Token in Path [#token-in-path] ``` BaseURL: https://api.deeplx.com/{{apiKey}} API Key: your-secret-token Result: https://api.deeplx.com/your-secret-token/translate ``` #### Token as Query Parameter [#token-as-query-parameter] ``` BaseURL: https://api.example.com/v1/translate?key={{apiKey}} API Key: your-api-key Result: https://api.example.com/v1/translate?key=your-api-key ``` #### Custom Endpoint with Token [#custom-endpoint-with-token] ``` BaseURL: https://deeplx.mydomain.com/api/{{apiKey}}/translate API Key: abc123 Result: https://deeplx.mydomain.com/api/abc123/translate ``` ## Setting Up DeepLX in Read Frog [#setting-up-deeplx-in-read-frog] 1. **Open Extension Options**: Click the Read Frog extension icon and go to Options 2. **Navigate to API Providers**: Go to the API Providers section 3. **Configure DeepLX**: * Set your **BaseURL** according to your provider's format * Add your **API Key** if required (leave empty for providers that don't need it) * Use `{{apiKey}}` placeholder if you need custom token placement 4. **Test Translation**: Try translating some text to verify the configuration works ## Common DeepLX Providers [#common-deeplx-providers] ### Free Providers (No API Key) [#free-providers-no-api-key] * `https://deeplx.vercel.app` * `https://deeplx.herokuapp.com` ### Paid/Self-hosted Providers [#paidself-hosted-providers] * `https://api.deeplx.org` (requires API key) * Your own self-hosted instance ## Troubleshooting [#troubleshooting] ### URL Construction Issues [#url-construction-issues] If you're having issues with URL construction: 1. **Check your baseURL format**: Ensure it follows the expected pattern 2. **Verify token placement**: Make sure `{{apiKey}}` is in the correct position 3. **Test without token first**: Try with a free provider to isolate configuration issues ### Common Errors [#common-errors] * **"API key is required when using `{{apiKey}}` placeholder"**: You specified `{{apiKey}}` in the baseURL but didn't provide an API key * **"DeepLX translation request failed"**: Check if your baseURL and API key are correct * **Network errors**: Verify the DeepLX provider is accessible and online ## API Response Format [#api-response-format] DeepLX providers should return JSON responses in this format: ```json { "data": "translated text here" } ``` If you're setting up your own DeepLX instance, ensure it returns responses in this expected format. # LM Studio (/en/docs/providers/lm-studio) ## What is LM Studio? [#what-is-lm-studio] [LM Studio](https://lmstudio.ai/) is a desktop app for downloading, managing, and running large language models locally. Its Local Server exposes local models through an OpenAI-compatible API, so Read Frog can connect to LM Studio through an OpenAI-compatible custom provider for local translation and reading. LM Studio's official OpenAI-compatible examples use `http://localhost:1234/v1`. The `1234` part is the Local Server port. In your own setup, always match the port configured in LM Studio's Local Server settings. ## Configure LM Studio Local Server [#configure-lm-studio-local-server] ### 1. Download and install LM Studio [#1-download-and-install-lm-studio] Download LM Studio from the [official website](https://lmstudio.ai/), install it, and download a model that fits your hardware. For translation, a smaller and faster model is usually better. For Read Frog's reading, summary, or structured-output features, choose a model that supports structured output. ### 2. Start Local Server [#2-start-local-server] In LM Studio, open **Developer** -> **Local Server**, make sure a model is loaded, then start the server. You can also start the server with the LM Studio CLI: ```bash lms server start --port 1234 --cors ``` If you use another port in the UI, such as `3000`, the Base URL in Read Frog must also be changed to `http://localhost:3000/v1`. ### 3. Configure Server Settings [#3-configure-server-settings] In **Developer** -> **Local Server** -> **Server Settings**, the recommended setup is: LM Studio Local Server settings | Setting | Recommended value | Notes | | ----------------------------------- | -------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------- | | Server Port | `1234` or your custom port | The Base URL port must match this value | | Require Authentication | On | Recommended, especially when CORS or LAN access is enabled; after enabling it, Read Frog must use an LM Studio API Token as the API Key to connect successfully | | Enable CORS | On | Browser extensions need cross-origin access to the local server | | Serve on Local Network | Off by default | Only enable it when other devices need access; require authentication if enabled | | Allow per-request MCPs | Off by default | Read Frog translation and reading do not need MCP unless you explicitly use it | | Allow calling servers from mcp.json | Off by default | This may let API clients call local MCP servers and is usually unnecessary | After CORS is enabled, websites or extensions from other origins can access the LM Studio API. It is strongly recommended to enable **Require Authentication** and only configure the API token in tools you trust. ### 4. Create an API Token [#4-create-an-api-token] Open **Server Settings**, enable **Require Authentication**, then click **Manage Tokens** to create a new API Token. Copy the token immediately after creation. LM Studio only shows it once. Then paste this token into Read Frog's API Key field. It is recommended to always enable authentication and paste a real LM Studio API Token into Read Frog. This prevents unauthorized clients from calling your local server when CORS or LAN access is enabled. ## Configure LM Studio in Read Frog [#configure-lm-studio-in-read-frog] ### 1. Open the API Providers page [#1-open-the-api-providers-page] 1. Click the Read Frog extension icon in the browser toolbar 2. Click **Options** 3. Open the API Providers / model provider settings page 4. Add an OpenAI-compatible custom provider Read Frog LM Studio provider configuration ### 2. Fill in connection settings [#2-fill-in-connection-settings] If your LM Studio Local Server uses the default `1234` port: ```json { "baseURL": "http://localhost:1234/v1", "apiKey": "Paste the API Token created in LM Studio", "model": "Select a model with Read Frog's Fetch Models action" } ``` If your Local Server port is not `1234`, update the Base URL: ```json { "baseURL": "http://localhost:XXXXX/v1" } ``` After configuring the Base URL and API Key, click **Fetch Models** in Read Frog to read the model list exposed by LM Studio Local Server, then select the model you want to use. If you need to verify the model list manually, you can also use: ```bash curl http://localhost:1234/v1/models \ -H "Authorization: Bearer YOUR_LM_STUDIO_TOKEN" ``` If authentication is disabled, remove the `Authorization` header. ### 3. Test the connection [#3-test-the-connection] After saving the provider, click **Test Connection**. If it fails, check: * LM Studio Local Server is running * Base URL ends with `/v1` * The port matches the Server Port in LM Studio * Enable CORS is turned on * If Require Authentication is enabled, the API Key is your LM Studio token * The loaded model identifier is correct ## Disable Thinking Mode [#disable-thinking-mode] Some models support thinking / reasoning mode, such as Qwen models. When enabled, the model may output reasoning content before the final answer. This can be useful for chat, but it can interfere with Read Frog's structured output and prevent translation information from being returned correctly. If translation contains reasoning text, output format becomes unstable, or JSON parsing fails, disable it in LM Studio: Disable Enable Thinking in LM Studio 1. Open the configuration panel for the loaded model 2. Go to **Model Parameters** -> **Custom Fields** 3. Turn off **Enable Thinking** 4. Save it as a no-thinking preset 5. Reload the model or apply the configuration when prompted The exact field name may vary by model. If you do not see **Enable Thinking**, the current model or runtime may not expose this option. ## Troubleshooting [#troubleshooting] ### Browser extension cannot connect [#browser-extension-cannot-connect] Make sure Local Server is running and **Enable CORS** is turned on. Browser extensions usually need CORS support when calling a local `localhost` service. ### 401 or authentication errors [#401-or-authentication-errors] If **Require Authentication** is enabled, requests must include `Authorization: Bearer `. In Read Frog, paste the LM Studio token into the API Key field. ### Port cannot be reached [#port-cannot-be-reached] `http://localhost:1234/v1` only works when the server port is `1234`. If you configured another Server Port in LM Studio, update the Base URL accordingly. ### LAN devices cannot access the server [#lan-devices-cannot-access-the-server] If another device needs to access LM Studio, enable **Serve on Local Network** and use the LAN IP of the machine running LM Studio, such as `http://192.168.1.10:1234/v1`. This increases exposure, so **Require Authentication** should also be enabled. ### Reading output has invalid format [#reading-output-has-invalid-format] Try disabling Thinking mode first, then switch to a model with better structured-output support. Some open-source models have weaker JSON-format reliability and may require a different model or simpler output requirements. ## References [#references] * [LM Studio Server Settings](https://lmstudio.ai/docs/developer/core/server/settings) * [LM Studio Authentication](https://lmstudio.ai/docs/developer/core/authentication) * [LM Studio OpenAI Compatibility](https://lmstudio.ai/docs/developer/openai-compat) * [LM Studio CLI server start](https://lmstudio.ai/docs/cli/serve/server-start) # Ollama (/en/docs/providers/ollama) ## What is Ollama Server? [#what-is-ollama-server] Ollama server is a lightweight, open-source AI model runtime platform that allows users to easily deploy various large language models (LLMs) and AI models locally without complex configuration. It acts as an "AI model manager," simplifying the tedious processes of model downloading, configuration, and runtime into just a few commands—making it accessible even for AI deployment beginners. ## Ollama Local Deployment Tutorial [#ollama-local-deployment-tutorial] ### Download the Installer [#download-the-installer] You can download the installer from [ollama.ai](https://ollama.ai/). ### Configure Ollama's Cross-Origin Support [#configure-ollamas-cross-origin-support] Please set the following environment variables: * Allow cross-origin access: `OLLAMA_ORIGINS=*` **macOS / Linux:** ```bash echo 'export OLLAMA_ORIGINS=*' >> ~/.zshrc source ~/.zshrc ``` **Windows (PowerShell in Administrator mode):** ```powershell [System.Environment]::SetEnvironmentVariable('OLLAMA_ORIGINS', '*', 'User') ``` After setting the environment variable, if you previously started the Ollama service, please close it first and then restart the `ollama serve` command. If you haven't started it yet, you can ignore this step. * API service listening address: `OLLAMA_HOST=127.0.0.1:11434` (This is the default address and can be left unchanged, but you can modify it based on your needs) ## Common Ollama Commands [#common-ollama-commands] ### 1. Check Ollama Version and Start the Server [#1-check-ollama-version-and-start-the-server] ```bash ollama version ollama serve ``` Use these commands to check the currently installed Ollama version, confirm successful installation, view version details, and start the Ollama server. ### 2. Find Available Models and Install [#2-find-available-models-and-install] You can find available models from [ollama.ai](https://ollama.ai/) and install them. ```bash ollama pull [model-name] ``` For example, to install the `gemma3:4b` model: ```bash ollama pull gemma3:4b ``` ### 3. List Downloaded Models [#3-list-downloaded-models] ```bash ollama list ``` This command displays all locally downloaded models, including names, sizes, and creation times, to help users manage local model resources. ### 4. Start the Service [#4-start-the-service] ```bash ollama serve ``` ### 5. Configure Ollama Provider in the Extension [#5-configure-ollama-provider-in-the-extension] In the extension settings, configure the Ollama provider and select a model. Ollama Provider If you did not change the default address, you can leave baseURL blank or set it to `http://127.0.0.1:11434`. If you changed the default address, you need to set the baseURL to the address you changed. ```json { "baseURL": "http://127.0.0.1:XXXXX/api" } ``` You can click the "Test Connection" button to verify if the connection is successful. ### 6. Notes [#6-notes] * Do not start Ollama Chat graphical client, it will compete with `ollama serve` for the port. * When configuring the Ollama provider in the extension, the baseURL defaults to `http://127.0.0.1:11434`, if your `OLLAMA_HOST` is this address, you can leave it unchanged. ## Troubleshooting [#troubleshooting] ### Windows: 403 Error When Connecting to Ollama [#windows-403-error-when-connecting-to-ollama] If you encounter a 403 error when the extension tries to connect to Ollama on Windows, it may be caused by running PowerShell (or the terminal) with administrator privileges. The elevated permissions can prevent the extension from properly accessing the Ollama service. **Solution:** Close the administrator PowerShell and restart `ollama serve` in a regular (non-administrator) PowerShell window. # OpenAI-Compatible Custom Providers (/en/docs/providers/openai-compatible-providers) ## Configure an endpoint [#configure-an-endpoint] In **Options → API Providers**, add an OpenAI-compatible provider, enter the Base URL, API key, and a model identifier, then enable it and use **Test Connection**. The endpoint must be reachable from the browser extension and implement the API operations used by the selected Read Frog feature. Use custom headers only when your service requires them, and keep secrets out of exported configurations. A custom model can translate text without supporting every AI feature. Custom AI Actions, Notebase structured results, and some context-aware workflows need reliable structured output; test those workflows separately from a simple translation. ## Troubleshooting [#troubleshooting] For authentication or network failures, verify the Base URL, API key, CORS/proxy policy, and provider account limits. For malformed structured output, choose a model with stronger JSON or structured-output support and disable reasoning output if available. Model availability and provider names change frequently, so use your provider's dashboard and the extension UI as the source of truth. # Request Control & Batch Translation (/en/docs/request-control) Open **Options → Translation → Request Control** to tune webpage request pacing. Video subtitles have an independent copy of these settings under **Options → Video Subtitles**. ## Defaults at a glance [#defaults-at-a-glance] | Setting | Default | Applies to | | ---------------------------- | ------: | ---------------------------------------------- | | Average Requests Per Second | `8` | All provider requests in that translation flow | | Maximum Burst Request Count | `60` | All provider requests in that translation flow | | Maximum Characters Per Batch | `1000` | LLM providers only | | Maximum Paragraphs Per Batch | `4` | LLM providers only | ## How the Token Bucket works [#how-the-token-bucket-works] Read Frog uses a continuously refilled Token Bucket: 1. The bucket starts full with **Maximum Burst Request Count** tokens. 2. Starting one queued request consumes one token. 3. **Average Requests Per Second** adds tokens continuously until the bucket is full again. 4. Whenever tokens are available, due requests can start. This distinction matters: **burst capacity is not a concurrency limit**. With the default capacity of `60`, a fresh bucket may immediately release up to 60 queued requests. The system does not promise that only 60 network requests will be in flight at once. Decimal rates are valid. A rate of `0.25` adds one token every four seconds; `0.5` adds one every two seconds. Do not copy a provider's “requests per minute” number directly into the per-second field. Divide it by 60, then consider whether that provider also limits short bursts. ## Choosing rate and burst capacity [#choosing-rate-and-burst-capacity] Match the sustained rate first, then choose how much initial traffic the provider accepts. | Provider quota example | Conservative starting point | | --------------------------------------- | ------------------------------------------------------------- | | 60 requests/minute, no documented burst | rate `1`, capacity `1` | | 15 requests/minute | rate `0.25`, capacity `1` | | 1 request every 10 seconds | rate `0.1`, capacity `1` | | High-throughput local model | keep `8` / `60`, then tune after observing latency and memory | If you receive HTTP 429 or quota errors, set capacity to `1` first and lower the rate to the provider's sustained limit. Increasing batching may reduce request count for LLMs, but it does not make an excessive burst safe. ## When LLM batching runs [#when-llm-batching-runs] Batch translation is used only when the selected provider is recognized as an LLM provider. Ordinary translation services continue sending their normal requests even when batch limits are visible. Compatible items share a batch when they have the same provider, source language, target language, and context. A batch is sent when any of these happens: * adding another item would exceed the character limit; * the paragraph/segment count reaches its limit; * the character count reaches its limit; * the short collection window (about `100` ms) expires. The `1000`-character and `4`-paragraph defaults balance request savings with predictable structured output. Larger batches can lower request overhead, but a slow or malformed result affects more paragraphs and may exceed a model or gateway limit. ## Structured results, retries, and fallback [#structured-results-retries-and-fallback] Read Frog expects one translated result for each source item in an LLM batch. If the model returns the wrong number of items, Read Frog retries that malformed batch up to three times, then falls back to individual translations for those items. Normal request failures are also handled by the request queue's retry policy; they are not the same as a batch-count mismatch. Duplicate in-flight items are deduplicated, and successful translations can be reused from cache. The **Statistics** page compares original paragraph requests with actual batched requests so you can confirm whether batching helps on your sites. Batch request savings shown on the Statistics page ## Practical presets [#practical-presets] ### Strict free tier [#strict-free-tier] * rate: the provider's documented per-second rate, often `0.1`–`1`; * burst capacity: `1`; * maximum characters: `600`–`1000`; * maximum paragraphs: `2`–`4`. ### Fragile structured-output model [#fragile-structured-output-model] Keep rate within quota, then reduce batches to `500`–`800` characters and `2` paragraphs. This trades request savings for more reliable one-to-one output. ### Fast local model [#fast-local-model] Start with the defaults. Increase batch size gradually while watching response time, memory use, and malformed batch fallbacks. A large burst can still overload a local server even when no remote quota exists. ## Page and subtitle settings are separate [#page-and-subtitle-settings-are-separate] Page translation and video subtitles do not share a bucket or batch configuration. Tune each workload under its own settings page. Subtitle traffic is often more time-sensitive, while webpage translation can tolerate a slower conservative rate. # Site Control & Site Rules (/en/docs/site-rules) Read Frog has two website controls with different purposes: | Feature | Location | Purpose | | ------------ | ------------------------ | --------------------------------------------------------------------------------- | | Site Control | **Options → General** | Allows or blocks the extension on whole hostnames using a blacklist or whitelist. | | Site Rules | **Options → Site Rules** | Changes how matching webpages are parsed, laid out, filtered, or styled. | Use Site Control for permission-like policy. Use Site Rules when Read Frog runs but chooses the wrong nodes, breaks inline text, translates code, or needs site-specific CSS. ## General Site Control [#general-site-control] Blacklist mode runs Read Frog everywhere except listed hosts. Whitelist mode runs it only on listed hosts. Hostname matching is exact or by subdomain: `example.com` also matches `news.example.com`, but it does not accept a URL path or wildcard syntax. This hostname-only format is also used by Translation's **Auto Translate Websites** and **Never Auto Translate Websites** lists. Never-auto affects automatic startup; General Site Control decides whether the extension runs at all. ## Site Rule URL patterns [#site-rule-url-patterns] Site Rules support richer URL patterns. Query strings are ignored during matching. | Pattern | Matches | | --------------------------- | ---------------------------------------------- | | `github.com` | HTTP or HTTPS pages on `github.com` | | `*.example.com` | the apex host and its subdomains | | `docs.example.com/guides/*` | guide paths on that host | | `https://example.com/*` | HTTPS pages only | | `www.amazon.*` | matching Amazon hosts across top-level domains | | `javdb*.com` | hostnames with matching text after `javdb` | Schemes may be `http`, `https`, or `*`. Explicit ports are rejected. Put exclusions in `excludeMatches` when a broad rule should skip a section of a site. ## How matching rules combine [#how-matching-rules-combine] Read Frog applies all matching enabled built-in rules first, then all matching enabled user rules. You can disable a built-in rule by its ID. * Selector lists are processed in order through their base, `.add`, and `.remove` fields. * `minCharacters` and `minWords` are scalar values; the last matching value wins. * `injectedCss` and `injectedCss.add` are concatenated in matching order. * A malformed URL pattern or selector is ignored and reported as a warning instead of being executed. This means a user rule normally has the final say, but arrays are not simply replaced. Use `.remove` to undo a selector introduced by an earlier rule and `.add` to extend it. ## Available fields [#available-fields] Every rule needs a unique `id` and `matches`. The editor accepts an object or array of objects; using an array is convenient for export and review. | Field | Meaning | | ---------------------------- | ------------------------------------------------ | | `id` | Stable, unique rule identifier. | | `description` | Optional human-readable purpose. | | `matches` / `excludeMatches` | URL pattern or list of patterns. | | `enabled` | Enables or disables the user rule. | | `excludeSelectors` | Nodes Read Frog must not translate. | | `includeSelectors` | Explicit areas Read Frog should consider. | | `forceBlockSelectors` | Treat matching nodes as block content. | | `forceInlineSelectors` | Keep matching nodes in the inline text flow. | | `preserveTextSelectors` | Preserve matching source text. | | `minCharacters` / `minWords` | Override small-paragraph filtering for the site. | | `injectedCss` | CSS inserted on matching pages. | Selector collections also support `.add` and `.remove`, such as `excludeSelectors.add` and `excludeSelectors.remove`. ## Safe example [#safe-example] Start with one narrow hostname, a few familiar selectors, and scoped CSS: ```json [ { "id": "example-docs", "description": "Translate article copy but leave navigation and code untouched.", "matches": ["docs.example.com/*"], "excludeSelectors": ["nav", "pre", "code", "[aria-label='Breadcrumb']"], "includeSelectors": ["main article"], "forceBlockSelectors": ["article p", "article li"], "preserveTextSelectors": [".product-name", ".command-name"], "minCharacters": 2, "minWords": 1, "injectedCss": ".read-frog-translated-content-wrapper { max-width: 100%; }" } ] ``` Save, reload one matching page, and inspect the result before broadening the pattern. Prefer CSS classes or semantic attributes that are stable across page loads. Generated class names often change after a deployment. ## Adjusting an earlier rule [#adjusting-an-earlier-rule] To extend or undo selector decisions from a matching built-in rule, add a later user rule: ```json [ { "id": "example-docs-adjustment", "matches": ["docs.example.com/*"], "excludeSelectors.add": [".sidebar-ad"], "excludeSelectors.remove": [".article-summary"], "forceInlineSelectors.add": [".term-with-tooltip"] } ] ``` This keeps the rest of the built-in rule while changing only the listed selectors. If the whole built-in rule is wrong, disable it instead of recreating every field. ## Validation and limits [#validation-and-limits] The editor validates JSON syntax, schema, duplicate IDs, selector and pattern syntax, rule count, and size before saving. Current limits are 200 user rules, 65,536 characters for the JSON document, and 8,192 characters for each CSS value. Injected CSS runs on every page matched by the rule. Keep patterns narrow, scope selectors to the target site, and avoid hiding security or account controls. ## Debugging checklist [#debugging-checklist] 1. Confirm General Site Control allows the hostname. 2. Confirm the rule is enabled and its `matches` pattern covers the current path. 3. Check `excludeMatches` and any disabled built-in rule. 4. Test selectors in the browser inspector against the current DOM. 5. Remove half the rule temporarily to isolate a selector, threshold, or CSS issue. 6. Reload the page after saving; already-processed nodes may retain the previous result. # Custom Subtitle Styles (/en/docs/subtitle-custom-css) The subtitle style page covers font, scale, weight, color and background opacity. Custom CSS is for everything those sliders do not reach: covering the translation with a blur until you actually need it, underlining it, pushing the original into the background, or reshaping the caption box. It applies to the Read Frog subtitle overlay only. Webpage translation has its own, separate stylesheet — see [Custom Translation Styles](/docs/custom-css). ## Open the editor [#open-the-editor] 1. Open **Options → Video Subtitles**. 2. Open **Subtitle style** with **Customize style**. 3. Scroll to **Custom CSS** and open it. 4. Write your CSS. The preview above the editor updates as you type. 5. Press **Save**. Saving reaches players that are already open, so you can keep a video in another tab and watch each save land. Clearing the editor and saving again removes the CSS and hands the subtitles back to the sliders. ## Start from a preset template [#start-from-a-preset-template] The **Preset template** dropdown carries three ready-made blocks. Choosing one **appends** it to the end of the editor rather than replacing what is already there, so templates stack: blur the translation *and* dim the original by picking two. ### Blur translation [#blur-translation] Listen first, and read only when you give up. The blur lifts while the pointer is over the line. ```css .subtitles-translation { filter: blur(6px); transition: filter 0.15s ease; } .subtitles-translation:hover { filter: none; } ``` ### Dashed translation [#dashed-translation] Marks the translation as a helper rather than the main text. ```css .subtitles-translation { text-decoration: underline dashed; text-decoration-thickness: 1px; text-underline-offset: 0.25em; } ``` ### Dim original [#dim-original] Keeps the source line available without letting your eye fall on it first. ```css .subtitles-main { opacity: 0.6; } ``` ## Selectors you can target [#selectors-you-can-target] The overlay is deliberately small. Three class names are part of the contract and will not be renamed: ```html
Mr. Kamiya isn't confronting the world…
神谷先生…
``` | Selector | What it matches | | -------------------------- | -------------------------------------------------------------------------- | | `.read-frog-subtitles-box` | the box both lines sit in — background, padding, corners, width, alignment | | `.subtitles-main` | the original caption line | | `.subtitles-translation` | the translated line | The translation line carries two extra hooks: * `lang` and `dir` follow your target language, so `.subtitles-translation[lang='ja']` and `.subtitles-translation[dir='rtl']` both work. * `data-pending="true"` is set while a translation is still on its way back. ```css .subtitles-translation[data-pending="true"] { opacity: 0.35; } ``` The original always comes first in the DOM; **Translation position** flips the two visually with `order`. Match on the class names rather than on `:first-child`. ## Working with the style controls [#working-with-the-style-controls] The font, scale, weight and color you pick in the UI reach each line as CSS variables that a stylesheet rule turns into declarations. Your CSS is injected after that rule, so an ordinary declaration wins — **`!important` is not needed**: ```css .subtitles-translation { color: #ffd479; font-weight: 600; } ``` Two exceptions are worth knowing before you spend time on them. ### Set the properties, not the `--rf-subtitle-*` variables [#set-the-properties-not-the---rf-subtitle--variables] The variables behind those four controls are written inline on each line, and an inline declaration outranks every stylesheet rule. Writing `--rf-subtitle-color` in custom CSS does nothing: ```css /* Ignored — the variable is set inline. */ .subtitles-main { --rf-subtitle-color: #7cf; } /* Works. */ .subtitles-main { color: #7cf; } ``` ### The box background needs `!important` [#the-box-background-needs-important] **Background opacity** is written inline on the box for the same reason, and this is the one place custom CSS has to insist: ```css .read-frog-subtitles-box { background-color: rgba(24, 20, 48, 0.85) !important; border-radius: 10px; padding: 8px 14px; } ``` Everything else on the box — padding, corners, width, alignment — takes a plain declaration. ### Size in `em`, not `px` [#size-in-em-not-px] The overlay's root font size is derived from the video's height, which is how subtitles stay proportionate when a video goes fullscreen or shrinks into a mini player. `1em` on a line means "the size the player would use"; a size in `px` freezes and stops following the video. ```css .subtitles-translation { font-size: 1.15em; } ``` ## More recipes [#more-recipes] ### Outline the text and drop the box [#outline-the-text-and-drop-the-box] Good on bright footage, where a dark plate is more intrusive than the captions themselves. ```css .read-frog-subtitles-box { background-color: transparent !important; } .subtitles-main, .subtitles-translation { text-shadow: 0 0 4px rgba(0, 0, 0, 0.95), 0 1px 3px rgba(0, 0, 0, 0.9); } ``` ### Let the translation lead [#let-the-translation-lead] Shrinks the source line to a reference and gives the translation the weight. ```css .subtitles-main { font-size: 0.75em; opacity: 0.65; } .subtitles-translation { font-size: 1.1em; font-weight: 600; } ``` ### Left-align long lines [#left-align-long-lines] Center alignment is hard to read once a caption wraps onto three lines. ```css .read-frog-subtitles-box { max-width: 70%; text-align: left; } ``` ### Per-language typography [#per-language-typography] Useful when you read in more than one target language and want each to look right. ```css .subtitles-translation[lang="ja"] { font-family: "Hiragino Mincho ProN", "Yu Mincho", serif; } .subtitles-translation[dir="rtl"] { font-size: 1.05em; } ``` ## Scope and limits [#scope-and-limits] The overlay is rendered inside a shadow root in the player. That boundary is what keeps your CSS from leaking onto the page — and it also decides what quietly does nothing: * **Works, and stays inside the overlay:** `@keyframes`, `@media`, `@supports`, transitions, pseudo-classes, and CSS variables you define yourself. * **Ignored:** `@font-face` and `@property`. A shadow root cannot register either, so pick fonts already available on the system instead of loading your own. * **Matches nothing:** `:root` and `body`. There is no page-level element inside the overlay — target the three classes above. * **Out of reach:** the YouTube player's controls, the page behind it, and the native captions. Custom CSS cannot style anything outside the subtitle overlay. * **Size limit:** 8 KB. The editor checks syntax as you type and blocks **Save** while the CSS is invalid or too long. ```css /* Animations are fine, and stay contained. */ @keyframes rf-fade-in { from { opacity: 0; } to { opacity: 1; } } .subtitles-translation { animation: rf-fade-in 0.2s ease-out; } ``` ## Troubleshooting [#troubleshooting] * **Nothing changed after saving:** confirm the status line reads *CSS is valid* and the button reads *Saved*, then check that the rule targets one of the three class names. * **A background color on the box is ignored:** add `!important`. The opacity slider writes that property inline. * **A `--rf-subtitle-*` override is ignored:** set `color`, `font-size`, `font-family` or `font-weight` directly instead. * **Text size jumps when going fullscreen:** switch that `font-size` from `px` to `em`. * **A font never applies:** `@font-face` does not work inside the overlay; use a font installed on the system. * **Save is disabled:** the editor found a syntax error, or the stylesheet is over 8 KB. * **The overlay looks broken:** empty the editor and save. The CSS is removed immediately and the style controls take over again. Custom CSS is stored with the rest of your settings, so it travels with a configuration export — see [Configuration, Sync & Backups](/docs/configuration). For everything else about the overlay, see [Video Subtitles](/docs/video-subtitles). # Tool Comparison (/en/docs/tool-compare) Read Frog specializes in in-depth language learning and is not merely a translation tool. It is designed for users of varying language proficiency levels, serving as a comprehensive reading tool. Currently, it supports detailed interpretations of words, phrases, and sentences from articles. In the future, features such as a vocabulary review system, user language level analysis, and eBook support will be added. ## Comparison with Traditional Translation Tools [#comparison-with-traditional-translation-tools] | Feature | Read Frog | Immersive Translator | Browser Built-in Translation | | ------------------- | ---------------------------------------- | ------------------------- | ---------------------------- | | Use Case | In-depth reading explanations | Simple translation | Simple translation | | Translation Quality | ✅ AI Translation | ✅ AI Translation | ❌ Poor Quality | | Translation Engine | 🟡 OpenAI, DeepSeek (more in the future) | ✅ 20+ engines | 🟡 Single engine | | In-Depth Learning | ✅ For language learners | ❌ None | ❌ None | | Price | ✅ Free | 🟡 Paid for some features | ✅ Free | | Open Source | ✅ Open source, customizable | ❌ Closed source | ❌ Closed source | | Privacy Protection | ✅ Local data storage | 🟡 Risk of data leakage | ✅ Local data storage | # Translation Tools (/en/docs/tools-and-settings) Read Frog provides four tools for translating without starting a full-page translation. Each tool can use a provider suited to its job; provider capabilities still apply. ## Floating button [#floating-button] Open **Options → Floating Button** to enable the button, place it on the left or right edge, and choose its click action. It can translate the current page directly or open the Read Frog side panel. The current expanded Read Frog floating button injected into a webpage Use **Disabled Websites** on this page to hide only the floating button on selected hosts. This is separate from General Site Control, which can prevent the entire extension from running. ## Selection toolbar [#selection-toolbar] Open **Options → Selection Toolbar** and select text on a webpage. The toolbar can expose: * **Translate** for a quick translation; * **Speak** for text-to-speech; * enabled **Custom AI Actions** for summaries, explanations, rewrites, or your own prompts. The current Read Frog toolbar displayed over selected text You can choose the translation provider, change toolbar opacity, configure disabled websites, and customize the keyboard shortcut. The default selection-translation shortcut is `Alt+T`. Custom AI Actions use the provider assigned to the action; the **Free AI Service** is available only for those selected-text actions and is not a full-page translation provider. ## Browser context menu [#browser-context-menu] Enable **Options → Context Menu** to add Read Frog to the browser menu shown after right-clicking selected text. It is useful when you prefer a native browser menu instead of an overlay. Read Frog translating selected text from the browser context menu Context-menu translation still needs an enabled compatible provider. Browser-managed pages and other protected pages may not allow extension content scripts. ## Input Translation [#input-translation] Open **Options → Input Translation**, enable the tool, and type three spaces in a supported editable field. Read Frog replaces the draft with its translation after the configured delay. Configure: * the translation provider; * how source and target languages are chosen; * fixed languages or cycling behavior; * the trigger delay (default `300` ms). The trigger is deliberately simple, so use it only after finishing the text you want translated. Input Translation follows General Site Control; unlike the floating button and selection toolbar, it does not have a separate disabled-website list. ## Which provider does each tool need? [#which-provider-does-each-tool-need] Ordinary translation services and LLM providers can translate selected text when supported by their provider adapter. **Custom AI Actions**, AI explanations, and similar prompt-driven tools require an LLM. Text-to-speech uses its own voice settings rather than a translation model. If a tool does nothing, check these in order: 1. the tool is enabled; 2. the current website is not blocked globally or for that tool; 3. its selected provider is enabled and passes **Test Connection**; 4. the page is not a protected browser or extension page. # Page and Paragraph Translation (/en/docs/translation) ## Translate a page [#translate-a-page] Use the floating button, the popup **Translate** action, or your configured page shortcut to translate the current page. In **Options → Translation**, choose **Bilingual** to keep source and translation together, or **Translation Only** for a cleaner translated page. You can translate the main content only or all eligible page content. The extension preserves the original page so you can switch modes again without reloading. Dynamic pages may translate as new content becomes available; content intentionally excluded by the website or a site rule is not translated. ## Translate a paragraph [#translate-a-paragraph] Enable hover or long-press translation in **Options → Translation** and choose its modifier key. Select text for the toolbar's Translate action, or use the context menu when it is enabled. The source and target languages come from your extension settings; change them before translating a page in a different language. For automatic behavior, request tuning, batching, and language skipping, see [Advanced Translation Settings](/docs/advanced-translation). For site-specific layout or selector exceptions, see [Translation Tools, Site Rules, and Settings](/docs/tools-and-settings). # Text to Speech (/en/docs/tts) Open **Options → Text to Speech** to configure the voice used by Read Frog's Speak actions. TTS is currently labeled **Public Beta**, but it does not require enabling Beta Experience. ## Where speech is available [#where-speech-is-available] The selection toolbar can show a **Speak** action for selected text. Other Read Frog surfaces may also expose speech when TTS is enabled. Translation providers do not generate the audio; Read Frog uses its Edge TTS voice configuration. ## Voice mapping [#voice-mapping] Assign a voice to each language you regularly read. Read Frog chooses the mapping for the detected language and falls back to the default voice when no language-specific mapping exists. Use the preview control before saving a mapping. Voice availability and quality can vary by language, operating environment, and the upstream speech service. If mixed-language text sounds wrong, add explicit mappings for both languages instead of relying on one default voice. ## Rate, pitch, and volume [#rate-pitch-and-volume] All three controls accept integer values from `-100` to `100`; the default is `0`. | Control | Lower values | Higher values | | ------- | ------------- | ------------- | | Rate | slower speech | faster speech | | Pitch | lower voice | higher voice | | Volume | quieter | louder | Start with small changes such as `-10` or `10`. Extreme combinations can sound unnatural or make speech difficult to understand. ## Troubleshooting [#troubleshooting] * **Speak is not visible:** enable it under **Options → Selection Toolbar**. * **Wrong language voice:** create a mapping for the detected language and preview it. * **No audio:** confirm the tab and operating system are not muted, then try another voice. * **Speech is clipped or unstable:** return rate, pitch, and volume to `0` and test again. * **Feature changes unexpectedly:** remember that TTS is Public Beta; export your configuration before a large voice-mapping change. Voice settings are included in configuration exports and backups. See [Configuration, Sync & Backups](./configuration) for recovery options. # Video Subtitles (/en/docs/video-subtitles) Read Frog can translate captions in normal YouTube videos, YouTube Shorts, and embedded YouTube players on other websites. The video must have captions that YouTube exposes to the player. A YouTube player showing bilingual subtitles ## Enable subtitle translation [#enable-subtitle-translation] 1. Open **Options → Video Subtitles**. 2. Enable **Video Subtitles**. 3. Select an enabled translation provider. 4. Open a supported YouTube video and use the Read Frog control in the player. The Read Frog translation control in a YouTube player **Auto-Enable Subtitles** starts Read Frog translation whenever a supported player loads. It does not manufacture captions: videos without available captions still cannot be translated. The auto-start setting for video subtitles ## Display and style [#display-and-style] Choose bilingual, original-only, or translation-only captions. For bilingual captions, place the translation above or below the source. Style controls include font family, size or scale, weight, text colors, background opacity, and player position. Video subtitle style controls These values affect the player overlay only. They do not change page-translation layout or [Custom CSS](./custom-css). For effects the controls do not cover — blurring the translation, dimming the original, reshaping the caption box — see [Custom Subtitle Styles](/docs/subtitle-custom-css). ## AI Smart Segmentation [#ai-smart-segmentation] AI Smart Segmentation uses an LLM to regroup raw caption fragments into more natural reading units. It can improve sentences split at awkward boundaries, but it: * requires an LLM provider; * adds model latency and token cost; * can occasionally make timing less exact; * stores a cached segmentation result for reuse. Clear the segmentation cache when you want the next playback to process the captions again. If subtitles disappear or lag, first turn segmentation off to separate caption availability from LLM processing. ## Independent request settings [#independent-request-settings] Video subtitles have their own provider, prompt, request rate, burst capacity, and LLM batch limits. Changing them does not change webpage translation. The defaults are `8` requests/second, burst capacity `60`, `1000` characters per batch, and `4` caption segments per batch. Rate and capacity use the same Token Bucket semantics described in [Request Control & Batch Translation](./request-control): capacity is an immediately available burst, not a concurrency limit. Batch translation applies only to LLM providers. For a low-quota subtitle provider, start with burst capacity `1` and the documented sustained rate. For example, `0.25` requests/second releases one request every four seconds. ## Troubleshooting [#troubleshooting] * **No Read Frog control:** confirm Video Subtitles is enabled, then reload the video tab. * **No translated captions:** verify that the video has captions and that the selected provider passes **Test Connection**. * **Frequent 429 errors:** lower the subtitle rate and set burst capacity to `1`. * **Awkward caption boundaries:** try AI Smart Segmentation with an LLM provider. * **Timing became worse:** disable Smart Segmentation or clear its cache and retry. The screenshots show the same controls described here; small visual details can differ as the YouTube player and extension UI evolve.